# Candidate Screening Matrix: Build One That Works
*Published 2026-09-15*
> Learn how to design a candidate screening matrix with weighted criteria, scoring rubrics, and role-specific examples that improve hiring decisions in 2026.
Source: https://www.talentpronto.ai/blog-posts/candidate-screening-matrix
---
A staffing manager has spent two days reviewing applications for one open medical assistant role. The queue still contains hundreds of resumes, reviewers disagree about which candidates deserve a phone screen, and the shortlist reflects whoever happened to open each application first. That process feels fast at the beginning, but it creates rework, inconsistent decisions, and explanations that are difficult to defend.
A **candidate screening matrix** turns that judgment into a repeatable comparison. It gives recruiters and hiring managers the same criteria, the same weights, and the same evidence-based scoring scale. The matrix won't eliminate judgment, and it shouldn't. It makes judgment visible, comparable, and easier to challenge before a weak process becomes a hiring decision.
## Table of Contents
- [When Gut Feel Stops Working](#when-gut-feel-stops-working)
- [What a Candidate Screening Matrix Is](#what-a-candidate-screening-matrix-is)
- [Choosing Criteria and Weighting Them Right](#choosing-criteria-and-weighting-them-right)
- [Start with the work](#start-with-the-work)
- [Separate gates from gradients](#separate-gates-from-gradients)
- [Assign weights by business impact](#assign-weights-by-business-impact)
- [Watch for resume visibility bias](#watch-for-resume-visibility-bias)
- [Building a Scoring Rubric With Anchored Levels](#building-a-scoring-rubric-with-anchored-levels)
- [One structure, different jobs](#one-structure-different-jobs)
- [Piloting, Auditing, and Stress-Testing Your Matrix](#piloting-auditing-and-stress-testing-your-matrix)
- [Test the proxies, not just the totals](#test-the-proxies-not-just-the-totals)
- [Protect independent judgment](#protect-independent-judgment)
- [Manual, Spreadsheet, or AI-Assisted Screening](#manual-spreadsheet-or-ai-assisted-screening)
- [Match the method to the funnel](#match-the-method-to-the-funnel)
- [Your Rollout Checklist and Common Questions](#your-rollout-checklist-and-common-questions)
- [Operational checklist](#operational-checklist)
- [Questions teams ask after launch](#questions-teams-ask-after-launch)
## When Gut Feel Stops Working
The volume problem appears differently across industries, but the failure pattern is familiar. A retail hiring manager may face **150 or more applicants for one posting**, while a tech requisition can attract **80 to 120 applications**. In healthcare, a single medical assistant opening can leave a staffing manager sorting through a crowded queue while also covering urgent operational work.
With three strong candidates, experienced judgment can be useful. With thirty, it becomes unreliable. One reviewer notices a polished job title, another prioritizes tenure, and a third gives extra credit to a resume that resembles their own career path. The same applicant can receive different verdicts because nobody has defined what “qualified” means in observable terms.
> **Practical rule:** If reviewers can't explain an advance or rejection using the same job-related evidence, the process isn't consistent enough for volume hiring.
A structured screening process gives each applicant a comparable path through the funnel. Reviewers assess the same dimensions, apply the same anchors, and record why a candidate received a particular score. That discipline also supports the broader [candidate screening process](https://www.talentpronto.ai/blog-posts/candidate-screening-process), especially when several recruiters or hiring managers share responsibility for one requisition.
The matrix isn't bureaucracy added to hiring for its own sake. It's a control against reviewer drift, post-hoc reasoning, and proxy signals that have little relationship to performance. It helps a team separate mandatory requirements from preferences, compare evidence across applicants, and identify where disagreement comes from. The rest of the process depends on getting those foundations right.
## What a Candidate Screening Matrix Is
A **candidate screening matrix** is a weighted scoring grid that converts role requirements into a documented score for each applicant. It has three working parts:
- **Criteria:** Job-related dimensions such as licensure, relevant experience, technical capability, or communication.
- **Weighting:** The share of the total score assigned to each dimension.
- **Anchored rubric:** Clear descriptions of score levels, tied to observable evidence rather than instinct.
The method has a research foundation. A widely cited meta-analysis reported structured interview validity at about **r ≈ .42**, compared with about **r ≈ .19** for unstructured interviews, placing structured formats at roughly twice the predictive strength for job performance ([structured interview validity research](https://startupkit.app/en/blog/structured-interview-scorecards-predictive-validity)). A second meta-analysis cited by that source places structured interviews near **r ≈ .51**, while work-sample tests appear around **r ≈ .54** in its comparison table.
A matrix applies structured decision-making before the interview. Resume screening evaluates application evidence, while an interview scorecard evaluates answers, exercises, and observed behavior during a consistent conversation. Keeping those stages distinct prevents reviewers from treating early impressions as interview evidence.
| Dimension | Screening Matrix | Interview Scorecard |
|---|---|---|
| **Timing** | Resume and application stage | Interview stage |
| **Evidence** | Credentials, experience, work samples, application responses | Standardized answers, exercises, and interviewer observations |
| **Primary use** | Decide who advances to an interview | Compare interview performance |
| **Scoring** | Weighted criteria with documented evidence | Anchored competencies tied to interview questions |
| **Audit trail** | Records why an application advanced or stopped | Records why an interview outcome was reached |
A useful matrix is auditable. A reviewer can trace every advance or rejection to a criterion, a score, and the evidence behind it. That record matters in specialized hiring, including efforts to [Hire Legal assistants](https://hireparalegals.com/hire-legal-assistants/) where document accuracy, confidentiality, client communication, and matter-management experience may all affect the decision.
The matrix also needs a bias check. A polished employer name, uninterrupted career history, or familiar credential can act as a proxy for access and social background rather than job performance. Review the criteria for that risk, then test the scoring rules against historic hires to see whether they would have screened out people who later performed well. Use AI to organize application evidence or flag missing information, but keep human reviewers responsible for the criteria and final interpretation. Independent reviewers should score evidence before seeing an automated recommendation.
The compliance backbone is the U.S. Uniform Guidelines on Employee Selection Procedures. The [EEOC guidance on employment tests and selection procedures](https://www.eeoc.gov/laws/guidance/employment-tests-and-selection-procedures) identifies content validity, criterion-related validity, and construct validity as ways employers can show that a selection procedure is lawful. It also advises retaining validation documentation, including documentation for vendor-supplied assessments.
## Choosing Criteria and Weighting Them Right
A matrix is only as sound as the criteria beneath it. Teams often make the mistake of converting every line in a job description into a scored requirement. That creates a wishlist, not a selection model.
### Start with the work
Pull criteria from three places: the actual job description, performance reviews of successful people in the role, and the hiring manager's intake discussion. Ask what the person must accomplish, what errors create operational risk, and which capabilities distinguish dependable performance from merely acceptable performance.
For a healthcare role, that may mean licensure, clinical judgment, documentation, and patient communication. For a retail role, it could mean transaction accuracy, team coordination, conflict handling, and shift availability. A tech role might require system design, incident response, and the ability to make sound trade-offs under changing requirements.
### Separate gates from gradients
Some requirements should be binary. A required certification, legally necessary license, or mandatory work authorization can function as a knockout filter when the role requires it. Don't turn a true prerequisite into a weighted preference.
Other attributes should receive graduated scores. Communication, problem-solving, domain knowledge, and relevant experience usually benefit from a rubric because candidates can meet them at different levels. The distinction keeps the matrix honest. A candidate either holds a required license, or they don't. Their communication evidence, however, may range from weak to exceptional.
### Assign weights by business impact
Weights should total **100 points** and reflect likely contribution to success, not how easy a requirement is to spot on a resume. A registered nurse matrix might allocate:
- **Clinical competency, 35 points**
- **Relevant specialty experience, 25 points**
- **Communication, 20 points**
- **Cultural fit, 15 points**
- **Availability, 5 points**
This example is a starting model, not a universal answer. The hiring team should test whether each weight reflects the consequences of success or failure in that role. Skills that predict first-year performance should generally outweigh skills that the employer can teach quickly.
Keep the weighted criteria to **about five to seven per role**, consistent with scorecard guidance from [structured interview design research](https://join.com/en/blog/structured-interviews-questions-that-predict). More dimensions may look thorough, but they increase reviewer fatigue and make scores harder to interpret.
### Watch for resume visibility bias
Degrees, prestigious schools, familiar employers, and polished job titles are easy to score because they are highly visible. They can also act as proxies for socioeconomic access, geography, or demographic patterns. A candidate screening matrix should reward evidence tied to the work, not the prestige of the context in which someone acquired it.
Use this reusable template:
| Matrix component | Working decision |
|---|---|
| **Role outcome** | What must this person accomplish? |
| **Mandatory gates** | Which requirements are genuinely non-negotiable? |
| **Scored criteria** | Which five to seven dimensions predict success? |
| **Weights** | How should 100 points reflect business impact? |
| **Evidence source** | Where will reviewers find proof? |
| **Review owner** | Who scores, calibrates, and audits the model? |
Teams looking for concrete [criteria scoring examples](https://www.overvue.ai/post/criteria-scoring) can use role-specific examples as a prompt, but they should still validate every criterion against their own work.
## Building a Scoring Rubric With Anchored Levels
A score without an anchor is an opinion wearing a number. To make a matrix dependable, define what each level means before anyone reviews an application.
A practical approach uses a **0 to 4 behavioral scale**:
- **4:** Strong, directly relevant evidence with clear outcomes, qualifications, or demonstrated depth.
- **3:** Solid evidence that meets the role's expected standard, with only minor gaps.
- **2:** Partial or transferable evidence, but the reviewer must verify capability.
- **1:** Limited, indirect, or weak evidence.
- **0:** No evidence, or evidence that fails a mandatory requirement.
The anchor must describe what a reviewer can observe. “Strong communicator” is too vague. “Presented project results to a cross-functional audience of 10 or more stakeholders” gives the reviewer something concrete to evaluate. Depending on the role, evidence may include relevant experience, certifications, demonstrated outcomes, portfolio work, or reference material.
### One structure, different jobs
The scale can flex across healthcare, retail, and technology without changing its logic.
| Role | Criterion (Weight) | Score 4 | Score 2 | Score 0 |
|---|---|---|---|---|
| **Registered nurse** | Clinical competency (35) | Current licensure plus direct evidence of handling the role's clinical demands and documenting patient care accurately | Related clinical exposure, but limited evidence in the target setting | No required licensure or no relevant clinical evidence |
| **Retail shift lead** | Conflict resolution (20) | Describes specific customer or team conflicts, the actions taken, and a constructive result | General service experience with limited detail about resolution | No evidence of handling conflict |
| **Senior backend engineer** | Incident response (25) | Shows ownership of complex incidents, diagnosis, communication, and durable remediation | Participated in incident response but gives limited evidence of ownership or follow-through | No relevant incident-response evidence |
For the registered nurse, a certification can support the score, but it shouldn't replace evidence of applying clinical knowledge. For the retail shift lead, a claimed shrink reduction number can be useful only when the candidate explains their contribution and the operating context. For the backend engineer, code review signals matter more when they show how the candidate improves reliability, clarity, and team decision-making.
Use the same scoring mechanics for hourly and salaried hiring, then change the evidence anchors. Hourly roles may emphasize POS fluency, attendance requirements, customer interactions, and shift leadership. Salaried roles may require deeper evidence of planning, influence, technical judgment, or sustained outcomes.
> A reviewer should know why a candidate received a 2 instead of a 3 without asking another reviewer what they “felt.”
The rubric also supports a structured interview later. The [interview scoring rubric](https://www.talentpronto.ai/blog-posts/interview-scoring-rubric) can extend the same criteria into standardized questions, preserving continuity between the application screen and the interview decision.
## Piloting, Auditing, and Stress-Testing Your Matrix
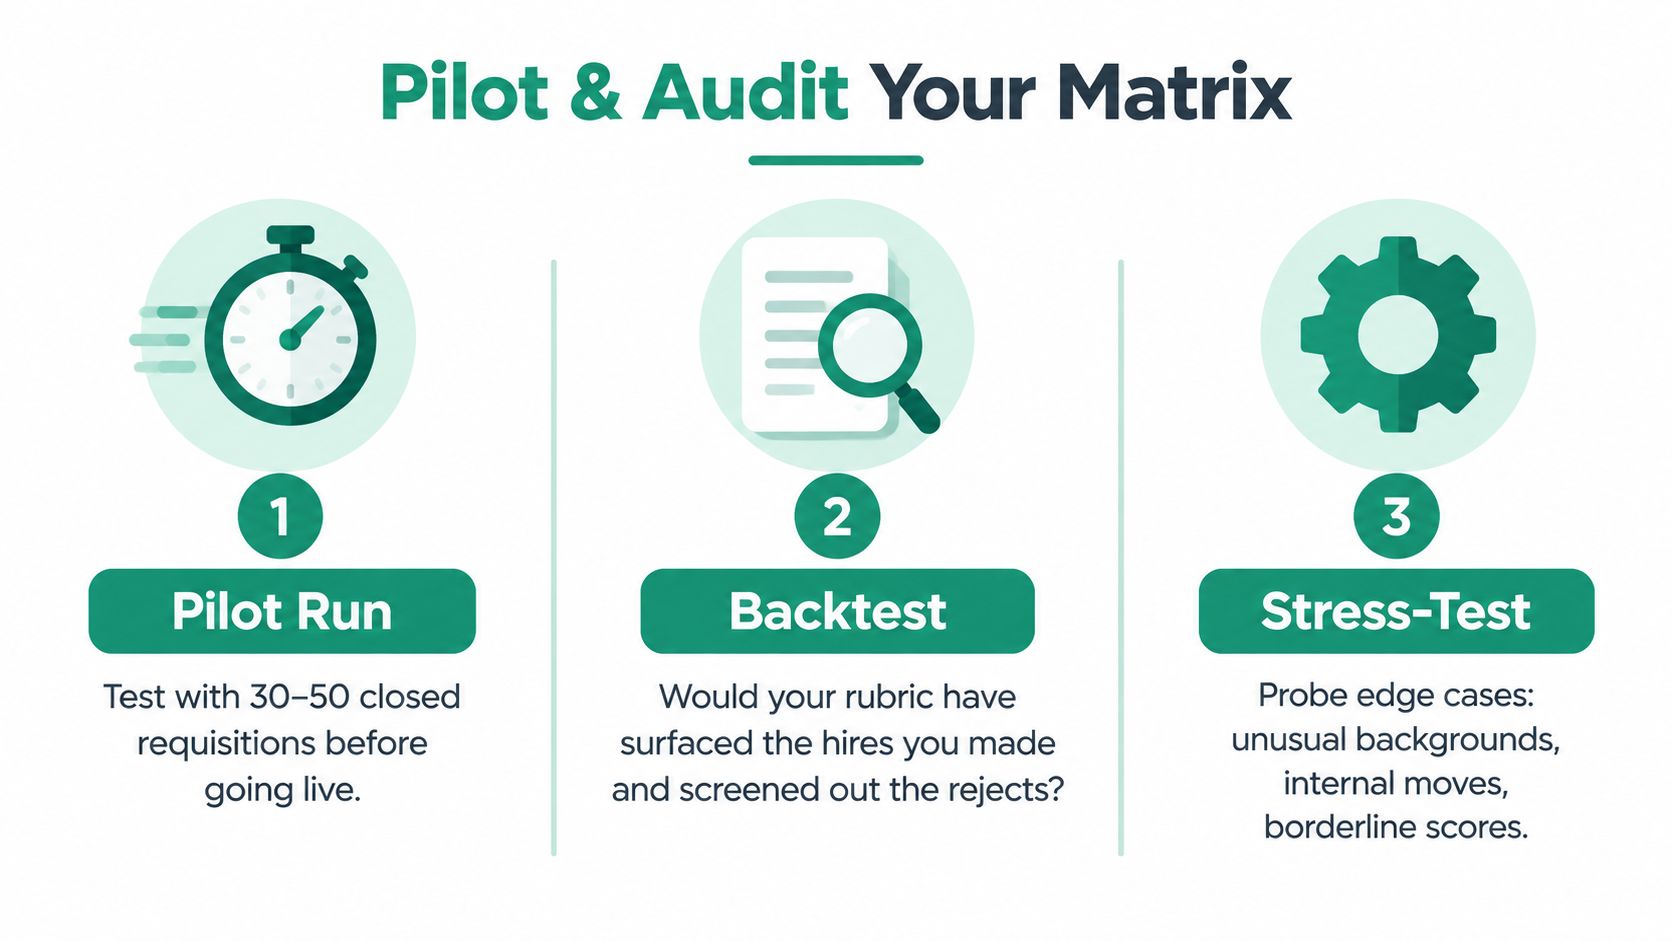
A matrix shouldn't go live because the hiring team likes how it looks. Pilot it against **30 to 50 closed requisitions** before relying on it for new hiring, as recommended in this [weighted candidate scoring method](https://zythr.com/resources/candidate-scoring-model-in-recruiting-what-it-is-and-how-to-build-one/how-to-build-a-weighted-candidate-scoring-matrix-stepbystep-template-and-examples). Ask two uncomfortable questions: would the model have surfaced the people you hired, and would it have screened out candidates who later churned in the early employment period?
### Test the proxies, not just the totals
Audit whether signals such as zip code, school prestige, or tenure at brand-name employers correlate with protected demographic categories. You don't need to assume that a criterion is discriminatory to test whether it may operate as a proxy. If a criterion produces a large difference in progression rates across protected groups, the team needs a job-related justification and evidence that the criterion is necessary.
The [EEOC recruiting and hiring guidance](https://www.eeoc.gov/employers/small-business/3-im-recruiting-hiring-or-promoting-employees) advises employers to apply the same standards to everyone applying for the same position, retain applications and interview notes for at least one year, and justify practices that have an especially negative effect on protected groups.
### Protect independent judgment
Have two reviewers score the same five candidates blind, then reconcile discrepancies above **1.5 points**. Record the reason for each disagreement. If the team only discusses scores after one senior reviewer has announced a preference, the group will often converge around authority rather than evidence.
Lock scores before the debrief. One analysis found that interviewers looking at each other's scorecards before submitting them increased exact rating agreement by **3.6%**, a result that illustrates the cost of contaminating independent judgment ([evidence on independent scoring](https://www.getsurfox.com/blog/candidate-screening-what-predicts-a-hire)). Capture inter-rater reliability as a percentage, identify the criteria driving the largest score swings, and revise anchors that invite interpretation.
The audit should also include AI outputs. Stanford reported in **2026** that AI hiring tools can show racial bias, so a matrix may look neutral while encoding proxy discrimination (Stanford's reporting on AI hiring bias). Version the matrix by role, record changes, and test edge cases such as career changers, internal applicants, nontraditional training, and employment gaps.
## Manual, Spreadsheet, or AI-Assisted Screening
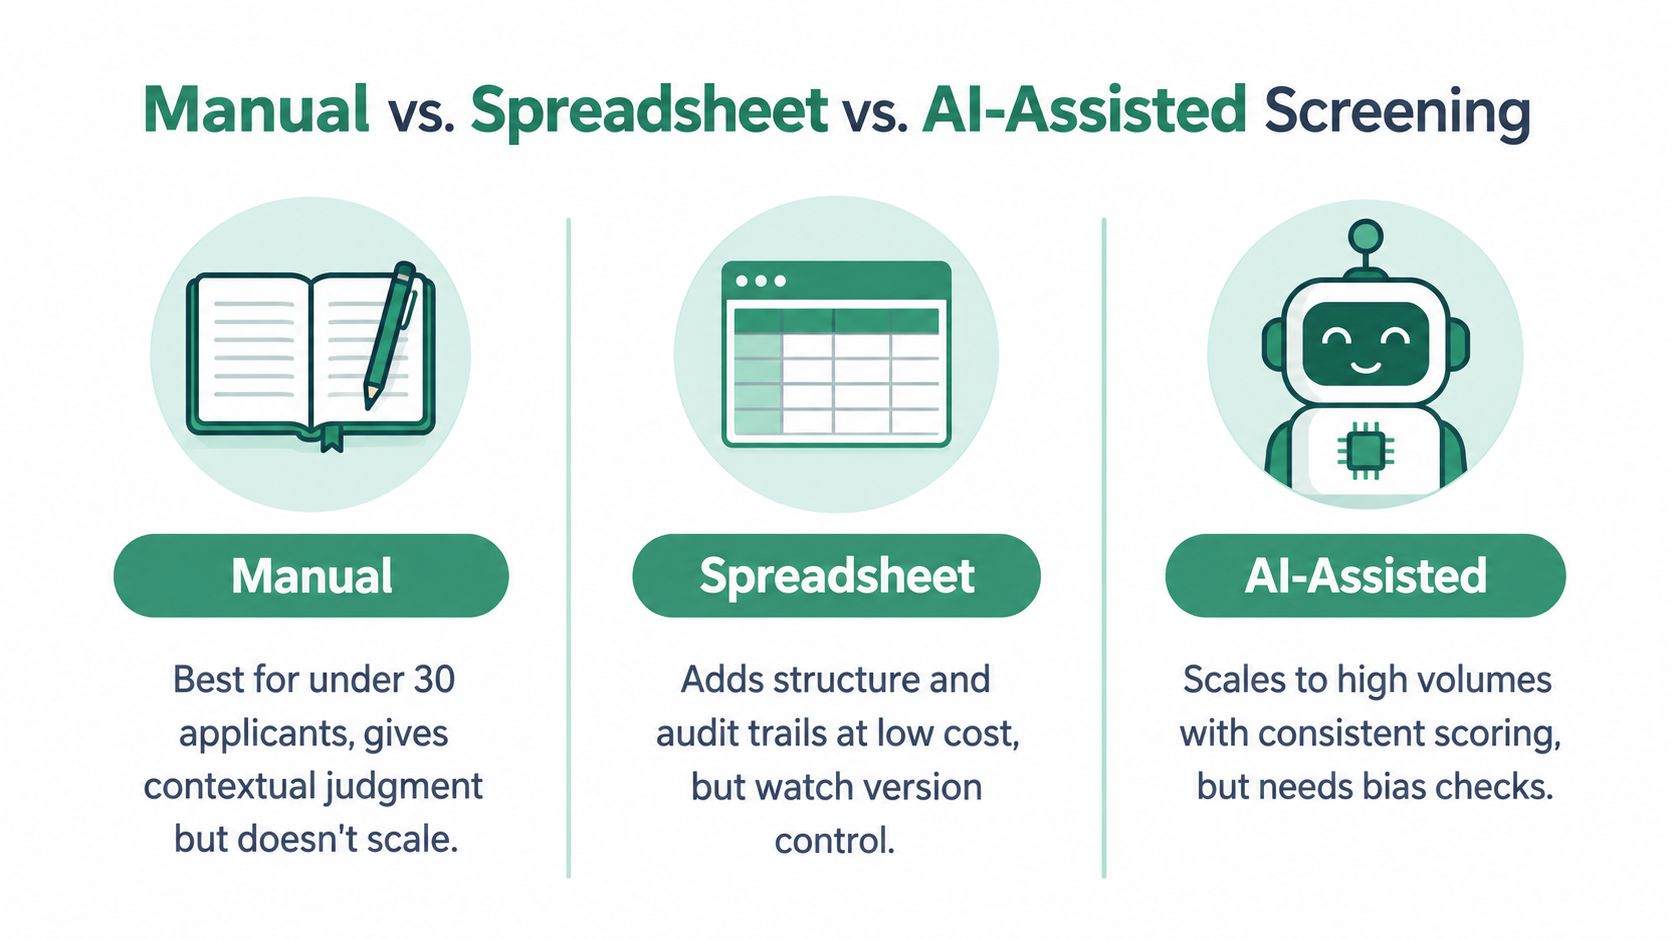
The right operating model depends on funnel size and risk. Manual review gives the richest context, but a person can't maintain careful, consistent attention indefinitely. A spreadsheet adds structure without a major technology project, while AI can process a large funnel but introduces a new layer that the team must validate.
### Match the method to the funnel
Manual review is usually appropriate for **under 30 applicants per role**, where the recruiter can read applications closely and document context. It doesn't scale well across many requisitions, and different reviewers may apply the same rubric differently.
Spreadsheets work well when a team needs transparency at low cost. They create a visible audit trail, make weighted formulas easy to inspect, and support calibration. Their weaknesses are practical: version-control problems, overwritten formulas, inconsistent data entry, and access management. Once more than five reviewers are editing the same file, those risks deserve active controls.
AI-assisted screening makes sense for **500-plus applicant funnels**, particularly in frontline healthcare, retail, hospitality, or other high-volume settings. Resume parsers, match scoring, and video analysis can reduce repetitive review, but each system creates a bias surface:
- **Training data drift:** The model may reflect historical decisions that no longer fit the role.
- **Keyword overfitting:** Candidates who use familiar wording may outrank people with equivalent experience described differently.
- **Career-path penalties:** Nontraditional backgrounds, career changes, internal mobility, and transferable skills may receive less weight.
- **Opaque rejection logic:** The employer may struggle to explain why an applicant was excluded.
> **Vendor rule:** Don't approve an AI rejection workflow until the vendor can explain where the model operates, how it was validated, and how your team can inspect or override its output.
Keep AI's role narrow and visible. It can parse resumes, ask standardized pre-screen questions, summarize evidence, or rank applications against a documented rubric. A human reviewer should remain in the loop for every rejection, and the employer should request validation studies and disparate impact ratios before signing.
Talent Pronto offers one example of an AI-assisted workflow. Its virtual assistant, Anna, conducts conversational screening, asks role-specific behavioral and technical questions, and prepares structured scorecards while leaving advancement and rejection decisions with the employer. Teams evaluating any platform should compare that workflow against their rubric, audit requirements, candidate disclosures, and ATS or HRIS integration needs. More background on automation choices appears in [automated candidate screening](https://www.talentpronto.ai/blog-posts/automated-candidate-screening).
A short demonstration can also help teams distinguish administrative automation from actual structured assessment.
Automation must also account for applicant trust. Industry reporting in **2026** cited survey data showing that **63% of U.S. candidates had been interviewed by AI in the prior 12 months**, while **38% withdrew from a process specifically because it included an AI interview** ([Greenhouse reporting on AI bias and candidate experience](https://www.greenhouse.com/blog/ai-bias-in-hiring)). Disclose the tool, explain what it evaluates, offer a non-AI path where feasible, and avoid turning consistency into a silent candidate filter.
## Your Rollout Checklist and Common Questions
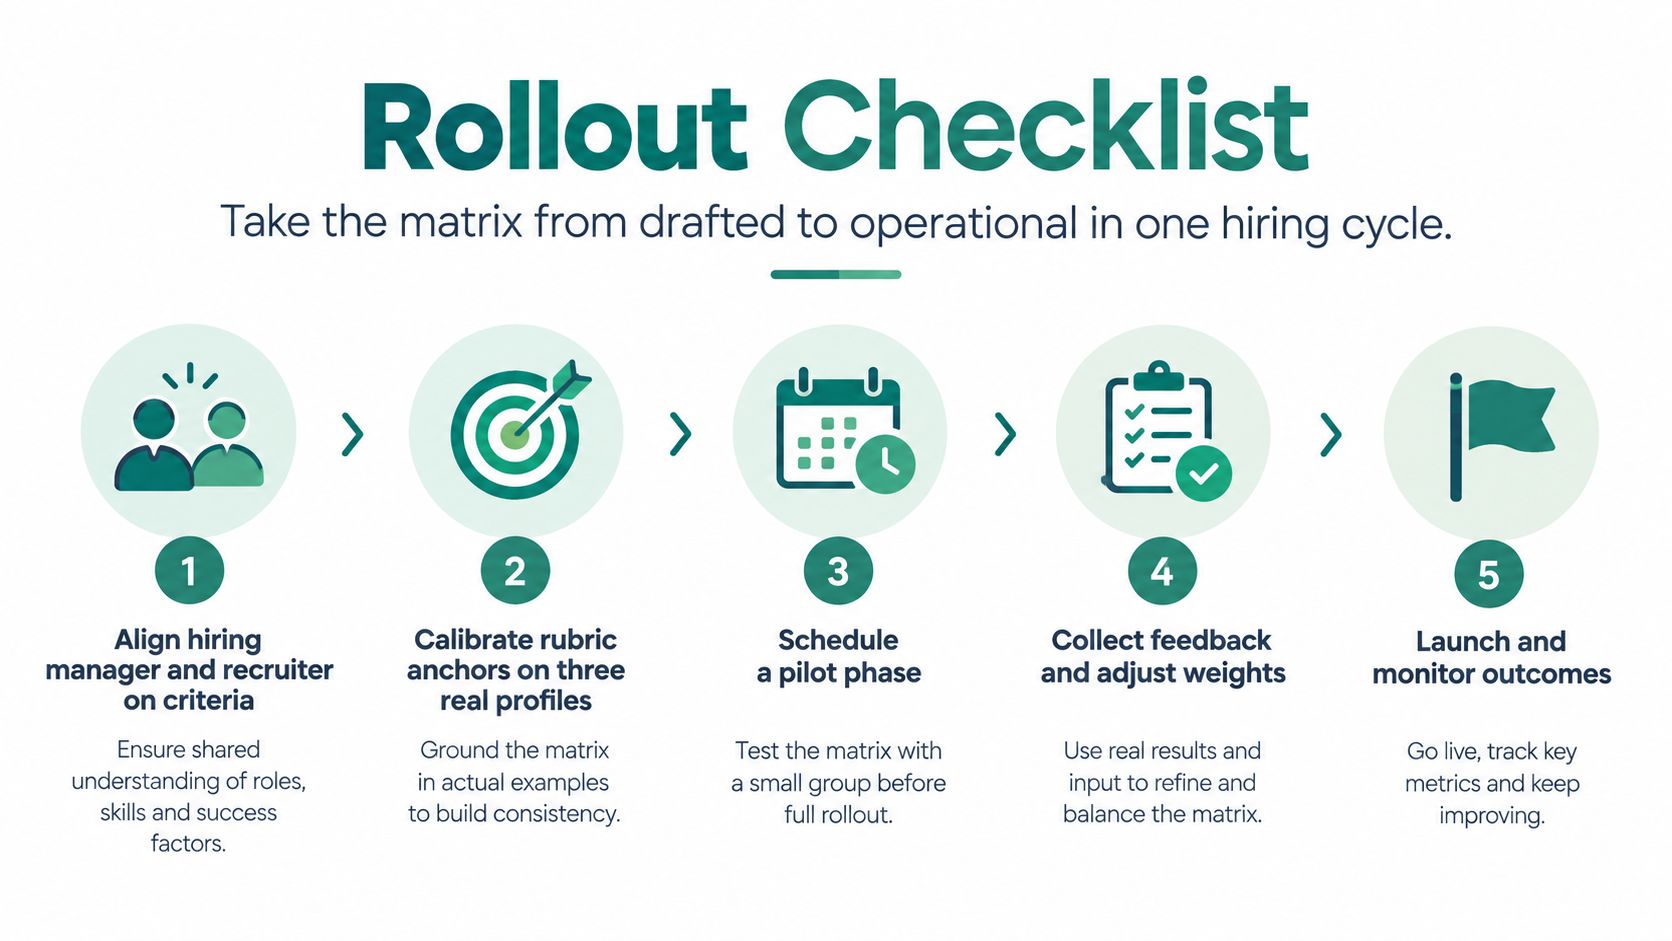
A matrix becomes useful when it changes daily decisions, not when it sits in a recruiting folder. Put it into operation during one hiring cycle with clear owners, documented evidence, and a scheduled review.
### Operational checklist
1. **Align the hiring manager and recruiter:** Agree on criteria, knockout requirements, evidence sources, and score ownership.
2. **Calibrate on three real profiles:** Apply the anchors to candidates who represent strong, borderline, and weak evidence.
3. **Lock the rubric before posting:** Don't adjust weights after seeing which applicants enter the funnel unless you document the reason.
4. **Record score rationale:** Save the evidence behind each application score, not just the total.
5. **Audit after the first ten screens:** Look for proxy signals, unexpected rejection patterns, and criteria that reviewers interpret differently.
6. **Revisit quarterly:** Compare outcomes, reviewer agreement, candidate feedback, and hiring-manager overrides.
### Questions teams ask after launch
**How many criteria are too many?** When reviewers struggle to distinguish scores or stop recording evidence, the model has too many dimensions. Keep the weighted set focused and put genuine prerequisites into knockout gates.
**Should internal and external candidates receive different scores?** The job-related standard should remain comparable. Internal applicants may offer additional evidence through known performance, but don't give them an automatic advantage unrelated to the role.
**What happens when reviewers disagree by more than two points?** Return to the anchor and evidence before debating the candidate. If the rubric can't resolve the disagreement, revise the criterion rather than forcing consensus.
**Should candidates see their scores?** Usually, share the process and evaluation areas rather than confidential comparative scores. Be accurate about what the tool or reviewer assessed.
**What if the hiring manager wants to override the matrix?** Allow documented overrides, but require the manager to state the job-related evidence that supports the exception. Overrides are useful signals about a flawed rubric, hidden requirements, or decision-maker bias. They shouldn't become a private route around the process.
The matrix exists to make the conversation after screening more honest. It doesn't replace professional judgment. It gives that judgment a record, a common language, and a chance to improve.
---
Talent Pronto helps hiring teams apply role-specific criteria through conversational screening, structured scorecards, candidate evidence, and ATS or HRIS workflows. Visit [Talent Pronto](https://talentpronto.ai) to see how its screening process can support consistent early-stage evaluation while keeping final hiring decisions with your team.