Build a faster, fairer candidate screening process from sourcing to scheduling. Includes step-by-step playbook, best practices, and metrics to track.
A hiring manager opens the applicant queue between clinical handoffs and sees a flood of resumes. The recruiter is already juggling requisitions, interview scheduling, and candidate follow-up. Everyone knows the role needs to move quickly, but nobody can agree on which applicants deserve human attention first.
That's the operational reality behind a modern candidate screening process. Screening isn't a clerical prelude to “real” hiring work. It determines who reaches a recruiter, who gets an interview, how consistently people are evaluated, and whether qualified candidates disappear because the employer took too long to respond.
A workable process treats screening as a measurable funnel with explicit criteria, structured evidence, human oversight, and compliance controls. The seven stages below show how to build that system without turning every role into an over-engineered assessment center.
A healthcare network's hiring manager returns from a code blue and finds 187 new applicants for one telemetry nurse posting. 140 applicants lack an active RN license, but the application system didn't ask the licensing question up front. The recruiter now has to inspect resumes manually, search for credentials buried in paragraphs, and determine whether each applicant can work the required shifts.
The recruiter spends the next 36 hours skimming profiles. By the time the hiring manager is ready to review candidates, patience has run out. The team interviews the first three applicants who look vaguely plausible, and the structured panel never gets assembled.
That failure starts at screening, not interviewing. A modern recruiting benchmark reports that only about 8% of applicants get past the initial screen, while roughly 0.5% ultimately receive an offer (Candidate.fyi's recruiting funnel benchmarks). The same benchmark estimates that about 35% pass the recruiter screen when measured stage to stage, compared with about 24% passing the onsite stage. The earliest screen removes the largest share of applicants, so a slow or poorly designed process constricts every later stage.
Weak screening creates interviewer fatigue. When a panel sees too many marginal candidates, members stop distinguishing evidence from impressions and begin approving whoever seems acceptable. That's how a hiring manager ends up rubber-stamping a candidate who merely survived a chaotic process.
It also creates fairness drift. If the team hasn't defined minimum qualifications and anchored scoring before applications arrive, recruiters and managers replace criteria with personal preferences. One reviewer favors prestigious employers, another favors tenure, and a third rewards polished communication even when it isn't central to the job.
Candidate silence causes a different kind of failure. Qualified applicants can abandon a process after an unexplained delay, especially when the employer's first contact arrives long after the application. Research on employer response timing reports that responsive recruitment processes typically see drop-off rates decrease by 40% to 60% (Quest Search's analysis of candidate drop-off).
Operational rule: If screening determines who gets attention, measure it like a production workflow, not like inbox administration.
The right question isn't “How many resumes did we review?” It's “How many qualified candidates moved through each stage, how quickly, and with what evidence?” That framing leads to a seven-stage funnel: sourcing, application, screen passed, assessment, interview, offer, and hire.
Before changing an ATS workflow, map the current funnel. The stage bands below provide a practical operating model for planning, not a promise that every role will land in the same range.
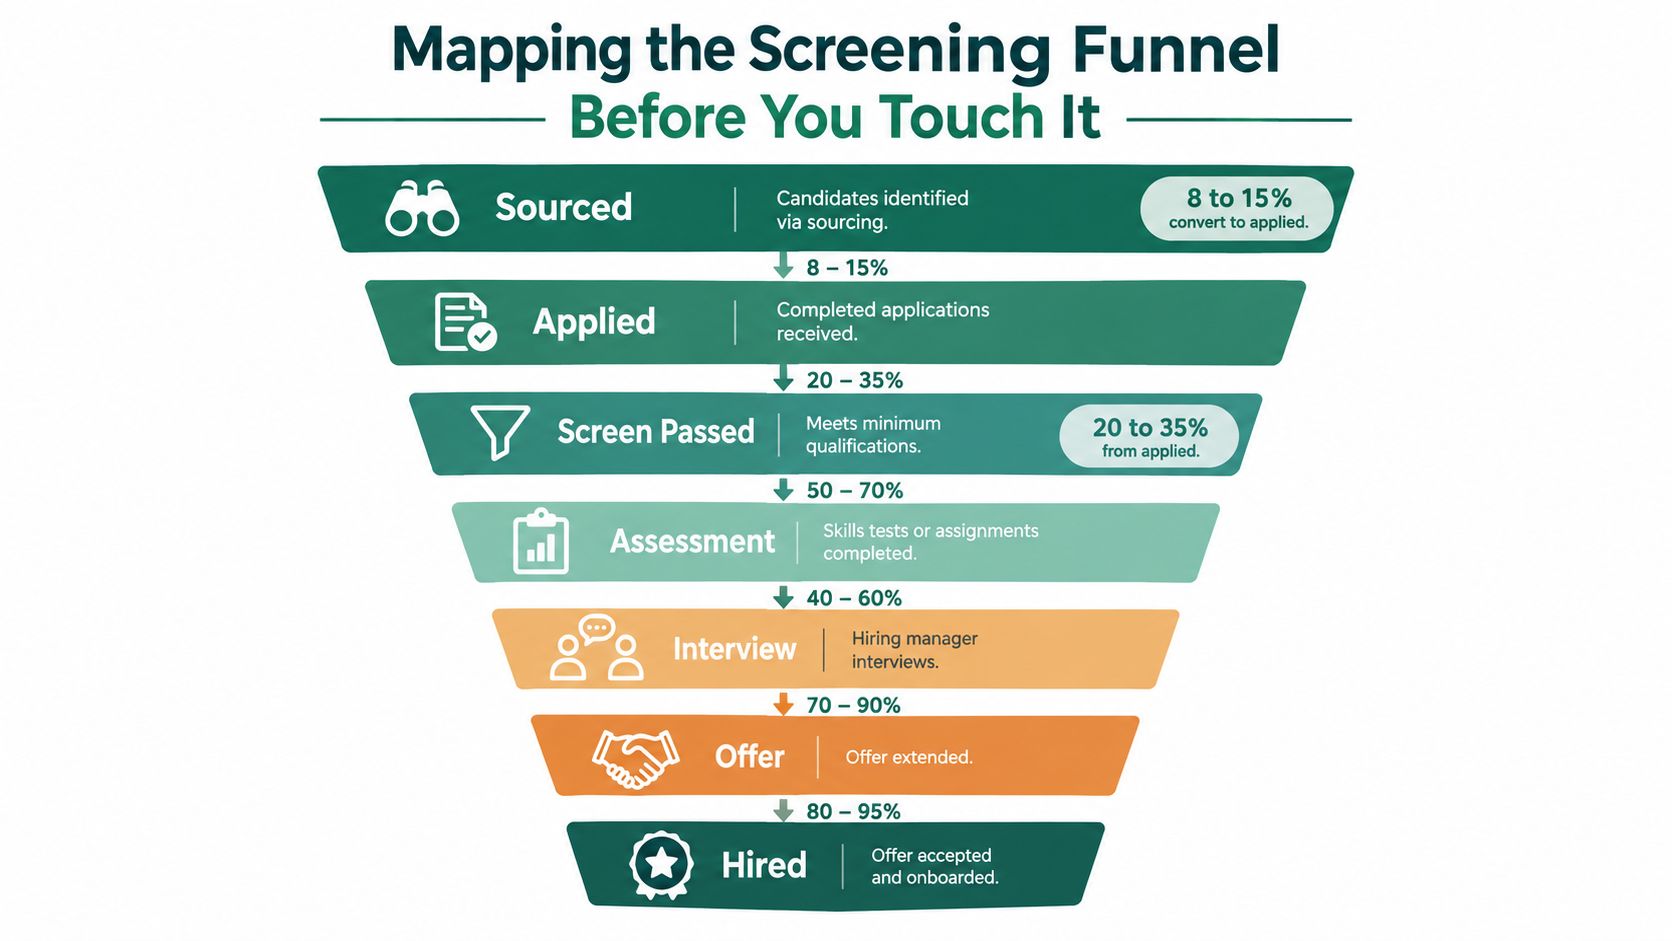
| Funnel stage | Practical conversion band | Common leak | Screening action |
|---|---|---|---|
| Sourced to applied | 8% to 15% | Poor job clarity or weak response to outreach | Improve the job description and confirm applications immediately |
| Applied to screen passed | 20% to 35% | Missing licenses, schedules, locations, or core qualifications | Add narrowly defined knock-out questions |
| Screen passed to phone interview | 60% to 80% | Recruiter backlog or unclear ownership | Set a screening queue and service-level target |
| Phone interview to onsite | 40% to 60% | Resume claims don't hold up in conversation | Use a structured phone screen |
| Onsite to offer | 25% to 40% | Panel inconsistency or inflated requirements | Tie questions and scoring to job-critical criteria |
| Offer to accept | 75% to 90% | Slow approvals or unclear terms | Give the candidate a fast, accurate handoff |
The sourced-to-applied stage leaks when outreach or job descriptions leave basic questions unanswered. An application confirmation reduces uncertainty and tells candidates what happens next. At the application stage, ask only true essentials. License status, shift availability, location, and work authorization can be appropriate knock-outs when they're required for the job.
The screen-passed-to-phone stage usually exposes operational delay. A candidate can meet every requirement and still vanish if the recruiter doesn't contact them promptly. The scheduler handoff matters here. Once a recruiter confirms fit, a scheduling tool such as GoodTime or Paradox should make the next action obvious rather than sending the candidate into an email loop.
Hourly manufacturing and retail roles typically require a volume funnel. Automation should handle repetitive qualification checks and rapid outreach, while humans focus on exceptions and motivation. Clinical and engineering roles need a depth funnel, because licenses, technical judgment, and specialized experience require more contextual review.
Don't redesign the funnel around industry averages alone. Pull your own stage counts from the ATS, separate requisitions by role family, and record where candidates exit. Establish that baseline before changing filters, scripts, or automation. Otherwise, you won't know whether a new workflow improved throughput or just moved candidates between mislabeled stages.
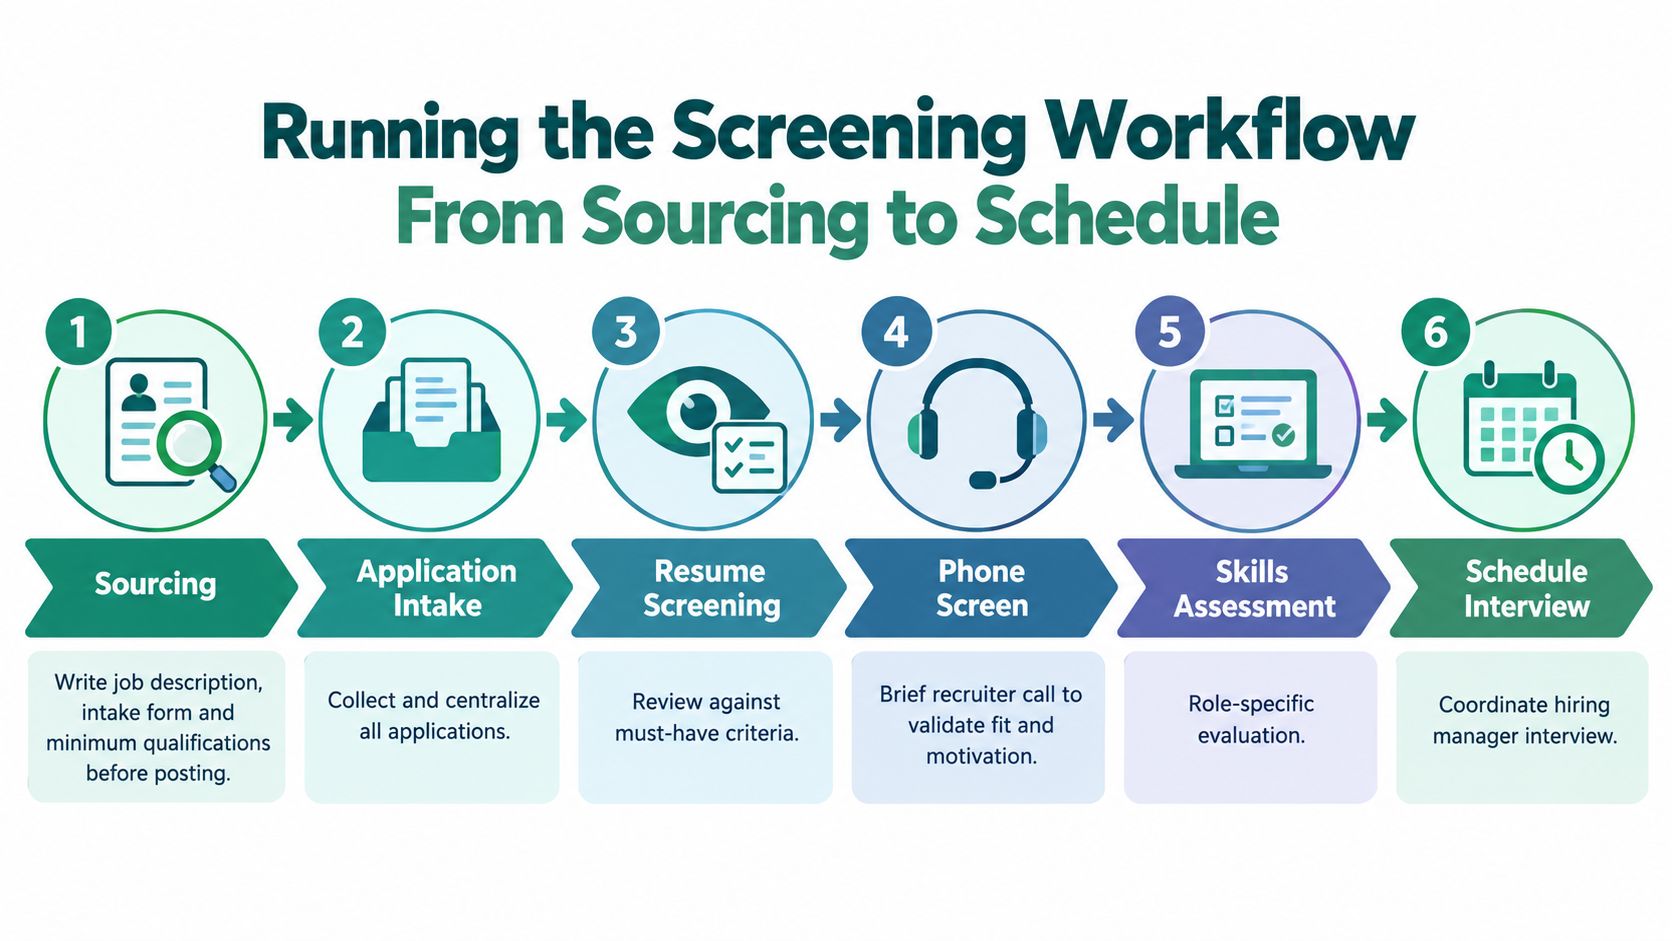
The workflow starts before the job is posted. Recruiter and hiring manager should complete the intake form, write the job description, and agree on minimum qualifications while the role is still being shaped. Criteria written after applications arrive tend to drift toward the resumes already in the queue, which turns screening into retrospective justification.
Applications should enter one system, such as Greenhouse or Workday, with required fields that capture genuine deal-breakers. For a licensed healthcare role, ask about the active license. For a plant role, ask about shift availability and location. For any role with a legal work requirement, ask the permitted question in a consistent, compliant way. Don't bury an essential requirement in a paragraph and then punish candidates for missing it.
Resume review should be a structured 90-second scan, not open-ended reading. Review the same fields for every applicant: required credential, relevant experience, evidence of core skills, location or schedule fit, and any follow-up issue. Record a specific reject reason such as “license inactive” or “required shift unavailable.” A vague note such as “not a fit” is useless for calibration, appeals, or process improvement.
For hourly roles, a 10-minute structured phone screen can cover three job-relevant criteria, such as safety behavior, attendance expectations, and experience with the required equipment. For clinical roles, a 15-minute panel-style screen can combine one behavioral question with a technical scenario. The objective isn't to conduct a full interview. It's to verify that the resume reflects usable capability and to identify questions for the next stage.
The handoff to the hiring manager should fit on one page. Include the scorecard summary, evidence supporting the recommendation, and two specific concerns that require validation. Then send a same-day scheduling link through GoodTime or Paradox so the candidate can choose an available time and receive a response inside four hours.
For sourcing messages, clarity matters more than cleverness. Recruiters who need to improve outreach can use Cold Email That Gets Replies as a reference for making the ask, role context, and next step easier to understand.
The scaling choice becomes clearer in practice. A manufacturing requisition with 80 applicants can use one recruiter, automated knock-outs, a fixed screen, and scheduling automation. A specialty search with eight applicants may justify two recruiters manually reviewing criteria, discussing technical evidence, and tailoring follow-up questions. Automation scales intake and coordination well. It doesn't replace judgment where the role depends on nuanced expertise.
The screening workflow also needs a candidate-facing explanation. Tell applicants what the first step involves, how long it takes, whether a human reviews the result, and how to request an accommodation. A fast process that feels opaque still damages trust.
No screening method wins across every role. Resume review is useful for context, keyword filtering is useful for narrow requirements, structured questions improve comparability, phone screens reveal how candidates reason, and conversational AI can handle always-on engagement when the employer has validated the workflow.
| Method | Time-to-decision | Fairness signal | Best for | Watch out |
|---|---|---|---|---|
| Resume-only review | Moderate to slow | Weak unless rubric-driven | Senior accountant context and career progression | Credentials can be buried or interpreted inconsistently |
| Keyword and ATS filters | Fast | Mixed | High-volume retail or manufacturing intake | Qualified candidates may use different language |
| Structured questionnaire | Fast | Strong when job-related | Licensing, availability, and baseline requirements | Too many questions increase abandonment |
| Structured phone screen | Moderate | Strong with anchored scoring | Maintenance leads, clinical roles, and customer-facing work | Untrained interviewers reintroduce subjectivity |
| Conversational AI screener | Fast and always available | Depends on validation and oversight | Large applicant pools and recurring roles | Accessibility, transparency, and model bias require active controls |
Keyword filters are a classic example of efficiency creating hidden losses. A nurse may place credentials in a prose summary rather than the exact field a parser expects. A maintenance lead may describe troubleshooting experience using plant-specific language that doesn't match the filter vocabulary. If the filter is the final decision, the system rewards formatting rather than qualification.
A structured phone screen remains valuable when tone, explanation, and judgment matter. For a maintenance lead, asking how a candidate isolates a recurring equipment fault can reveal sequencing and safety thinking that an AI chat may not capture reliably. For a high-volume retail role, a short questionnaire followed by selective human review may be enough.
The best method is the lightest one that reliably surfaces the role's must-haves without discarding qualified applicants at scale.
Use a primary method for the dominant signal and a backup for the predictable blind spot. Retail might use structured application questions first, then a short human screen for availability and customer judgment. A senior accountant role might start with resume review against a rubric, then use a work sample to verify reconciliation or reporting skill. A clinical role might combine credential verification with a structured technical conversation.
Teams hiring for specialized people operations and assessment work can also review IO psychology jobs with no call to understand how evaluation-oriented roles are presented without relying on phone-heavy processes. For broader workflow design, compare the implications of automated candidate screening, especially where automation handles repetitive work but employers retain decision authority.
Conversational screening is operationally distinctive but still uncommon. A 2026 hiring-automation report found that only 11% of organizations use role-specific qualification early, 11% deploy assessments during the application flow, 7% automate interview scheduling inline, and just 1% use voice-based screening agents (Aptitude Research's State of Hiring Automation 2026). That rarity makes validation more important, not less.
A scorecard works only when two reviewers can look at the same evidence and reach comparable conclusions. Writing a list of competencies isn't enough. Each criterion needs a definition, behavioral anchors, a rating scale, and a process for resolving disagreement.
Start by separating must-haves from nice-to-haves. An active clinical license may be a must-have. Experience with a particular electronic health record may be desirable but trainable. A knockout skill should be able to override a stretch preference, otherwise the scorecard becomes a weighted suggestion rather than a decision tool.
For each criterion, write three to five behavioral examples across strong, adequate, and weak performance. “Good communicator” is not an anchor. “Explains a safety escalation in a clear sequence, names the decision point, and confirms the handoff” is observable evidence.
| Criterion | Weight | Strong (3) | Adequate (2) | Weak (1) |
|---|---|---|---|---|
| Safety judgment | High | Identifies risk, follows escalation path, and explains why | Recognizes obvious risk but needs prompting | Minimizes risk or skips escalation |
| Technical troubleshooting | High | Uses a repeatable diagnostic sequence and validates the fix | Solves familiar issues with limited explanation | Guesses, skips checks, or can't explain the approach |
| Shift reliability | Medium | Gives clear evidence of meeting comparable shift demands | Can meet the schedule with stated constraints | Cannot meet an essential schedule requirement |
| Team communication | Medium | Provides concise handoffs and adapts detail to the audience | Communicates basic information adequately | Leaves gaps or blames others for missed information |
Run calibration before the first live screen. Have two recruiters independently score the same three sample applications, then compare the evidence behind each rating. Don't resolve the gap by averaging scores. Decide whether the anchor is unclear, the evidence is missing, or one reviewer is applying an unstated preference.
A rigid script can create the appearance of consistency while preserving poor judgment. Interviewers may memorize the question order, rush candidates toward expected answers, and ignore useful evidence because it doesn't fit the script.
Keep the criteria and core questions fixed, but allow the order to rotate and permit evidence-based probes. Ask, “What did you personally do?” or “What happened after that decision?” when an answer lacks detail. The standard is consistent evaluation, not identical conversation.
Use a minimum of two independent scores per screen. Set a one-point discrepancy trigger for discussion before the hiring panel. This gives the team a practical control against one reviewer's enthusiasm or skepticism dominating the result.
An evidence-based interview scorecard should compare candidates on the same competencies, use a consistent scale, and retain written evidence rather than gut feel. The scorecard source itself emphasizes that shared criteria make decisions comparable across candidates (Metaview's interview scorecard template).
Speed and AI aren't free wins. A screening process can reject people faster, lose qualified applicants through inaccessible design, and create an audit problem that nobody notices until a candidate or regulator asks how the decision was made.
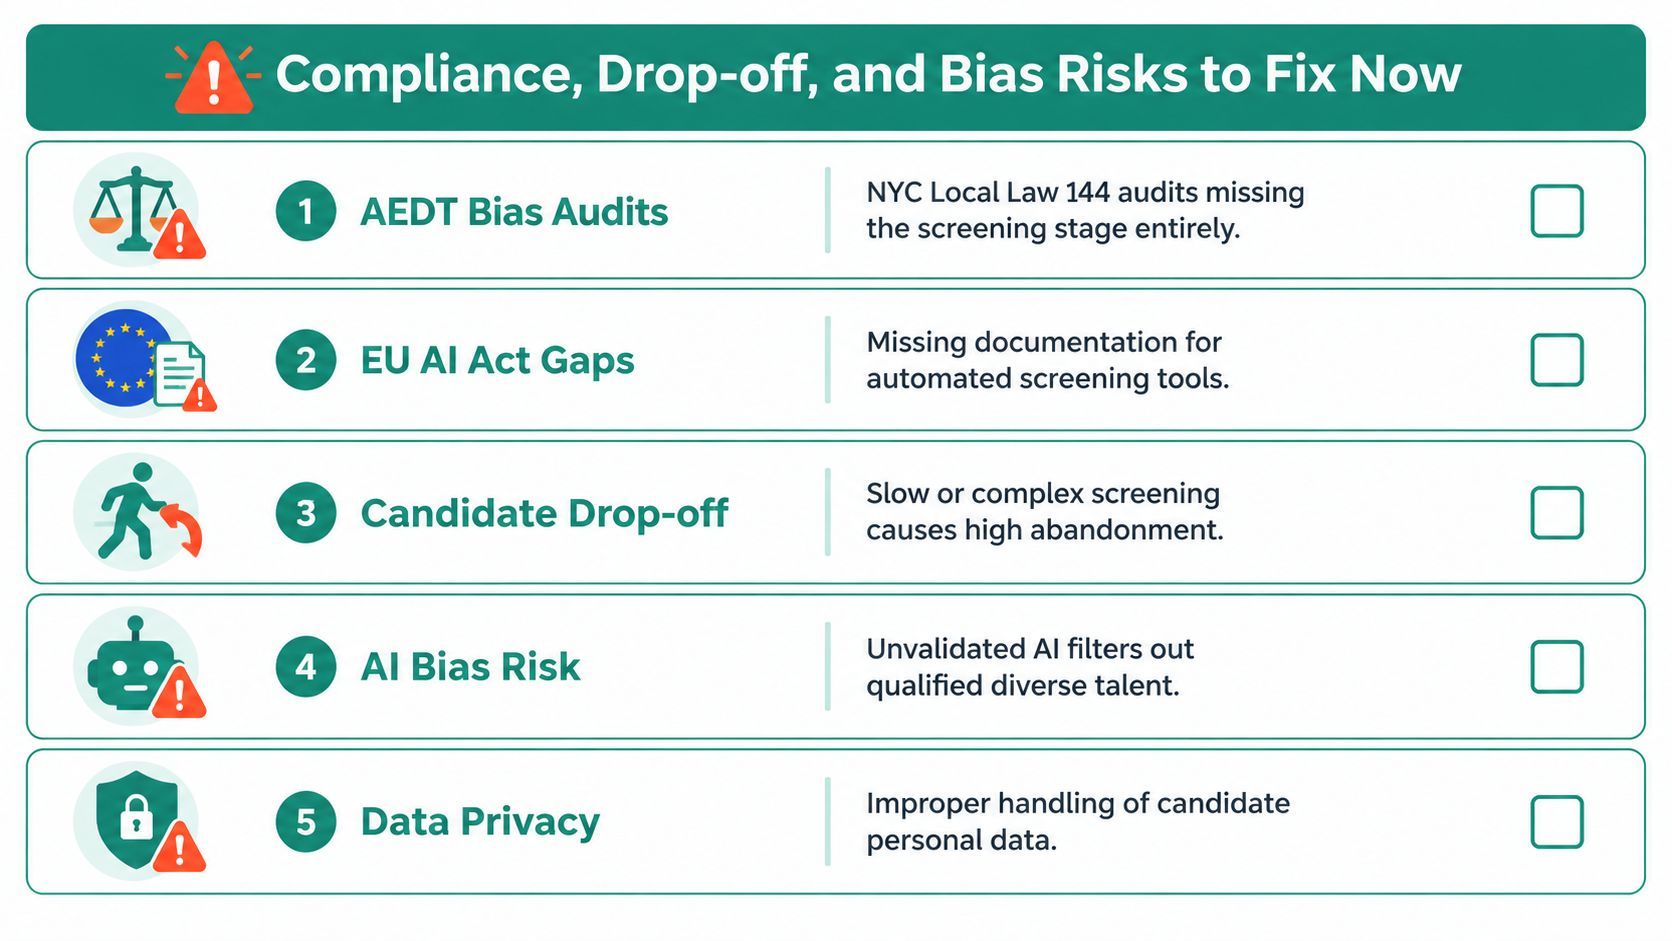
New York City's AEDT rules require an independent bias audit at least every 12 months and candidate notice before use. In the EU, recruitment AI is treated as high-risk, with requirements involving technical documentation, human oversight, logging, transparency, and bias monitoring. A recent regulatory update also moved the EU AI Act application date for some standalone high-risk systems to December 2, 2027 (Glider's coverage of AI hiring compliance).
Long silences, opaque automation, and accessibility barriers are recurring unfair hiring practices, not merely branding problems (Sapia's guidance on unfair hiring practices). Track who leaves at each stage and why. A funnel that improves speed by losing a particular group is not healthy.
“Resumes reviewed” is a productivity vanity metric. It rewards activity even when reviewers are processing the wrong applicants, moving too slowly, or producing shortlists that hiring managers reject.
Track four measures instead.
| Metric | Healthy range | ATS source | Alert threshold |
|---|---|---|---|
| Stage-by-stage conversion | Role-specific baseline | Funnel report by requisition and role family | Investigate a drop greater than 15% from baseline |
| Time-to-screen | Defined service target | Application timestamp to first screen decision | Alert when the target is missed repeatedly |
| Drop-off by demographic group | Compare with applicant-pool composition where lawful | Stage report joined to voluntary demographic data | Investigate unexplained divergence |
| Scorecard inter-rater agreement | At least 0.7 for the chosen reliability measure | Scorecard export or analytics warehouse | Review calibration when agreement falls below 0.7 |
The stage conversion rate tells you where the funnel narrows. Pull sourced, applied, passed, interviewed, offered, and hired counts from Greenhouse, Workday, or another ATS, then split the view by role family. A single company-wide average hides the difference between a manufacturing volume funnel and a specialty clinical search.
Time-to-screen should measure the elapsed time from application to a recorded screening decision, not the time a recruiter spends clicking through a profile. Pair it with first-contact timing because an applicant can be technically reviewed while still receiving no useful response.
For drop-off, compare applicant-pool composition with shortlist and interview composition where lawful. The point isn't to force identical outcomes. It's to identify a stage where a requirement, interface, delay, or evaluator behavior deserves investigation.
Scorecard agreement needs a real sample, not a feeling. Have two screeners rate the same 20 candidates, export the weighted ratings, and calculate weighted kappa. The result shows whether reviewers are applying the rubric consistently, particularly when a one-point difference matters near the advancement threshold.
Set baselines using the last four quarters of data where the records are reliable. Review the funnel weekly with recruiters, monthly with hiring managers, and quarterly with compliance. When conversion drops more than 15%, or agreement falls below 0.7, pause the reflex to blame candidate quality. Check the question, filter, timing, scoring anchor, and handoff first.
Talent Pronto offers 24/7 conversational screening, role-specific behavioral and technical questions, customized rubrics, structured scorecards, candidate outreach, and ATS or HRIS integrations with platforms including Greenhouse, iCIMS, Paylocity, ADP, and Workday. Visit Talent Pronto to assess whether its always-on screening and funnel reporting fit your high-volume hiring workflow.

Talent Pronto is an AI-powered hiring platform built around Anna, our intelligent AI that conducts 24/7 conversational screening, evaluates candidates against specific job requirements and compliance needs, and schedules interviews. Run everything on the Talent Pronto ATS, our all-in-one applicant tracking system with a branded careers site and Anna built in, or keep your existing ATS and let Anna integrate with Greenhouse, Ashby, iCIMS, Jobvite, Lever, Oracle, and more. Either way, we help organizations reduce time-to-hire and build stronger teams.