Learn what AI scores mean in hiring, how they are calculated, and how employers can use them fairly alongside human review for stronger hiring decisions.
85% of audited AI hiring systems scored above the 0.8 impact-ratio threshold across all tested demographic groups, while the average impact ratio for AI-powered selection was 0.94. An AI score is a structured, weighted number an automated system assigns after evaluating resume data and conversational responses against a role-specific rubric, but the final hiring decision remains with the employer.
A recruiting lead at a mid-sized company might open a dashboard and see a neat list of candidates ranked from highest to lowest. The numbers look precise, but precision isn't the same as truth. The useful question isn't whether the system produced a score. It's whether the score reflects job-relevant evidence, behaves consistently, survives fairness testing, and helps a trained hiring team make a better decision.
That distinction matters because AI-based scoring now appears across several recruitment stages, including CV ranking, advertising, and automated video interview scoring. A 2023 multidisciplinary survey on algorithmic hiring describes algorithmic hiring as a distinct research field because these systems operate across different data types and points in the funnel.
Suppose a recruiting lead has received a stack of candidate scores from an automated tool. One applicant has an 86, another has a 72, and a third has a 64. The lead wants to know whether the 86 is stronger or easier for the system to recognize.
An AI score in hiring is usually a weighted output. The system parses submitted information, evaluates structured responses, maps evidence to role criteria, and combines those results into a composite number. The rubric might assess relevant experience, technical knowledge, problem solving, communication, or other capabilities defined during job analysis.
The score is a ranking aid, not a verdict. It tells the employer how closely the available evidence matches the configured criteria. It doesn't prove that a candidate will succeed, and it doesn't replace reference checks, accommodations, interviewer judgment, or the employer's legal and operational responsibilities.
Vendors use several labels for similar outputs:
These terms aren't interchangeable in every product. A skeptical buyer should ask what each number includes, whether higher always means stronger alignment, and whether the scale is absolute or relative to the current applicant pool.
A raw model output is the mathematical result generated by a model before an organization maps it to a recruiter-facing scale. A calibrated rubric score applies business definitions, rating anchors, normalization rules, and validation checks so that the number has a stable interpretation.
For example, a raw output might represent the model's internal confidence that a response contains evidence of conflict resolution. A calibrated rubric could translate that evidence into a defined competency level, then combine it with other role criteria. Calibration doesn't make the number infallible. It makes the scoring logic visible enough to test.
The sections that follow focus on the practical questions behind that number: how the score is calculated, how reliability is assessed, how fairness can fail at the role level, and where human review must remain in control.
A useful way to understand AI scoring is to follow one candidate record through the complete pipeline. The system starts with messy information and ends with a standardized output that a recruiter can interpret.
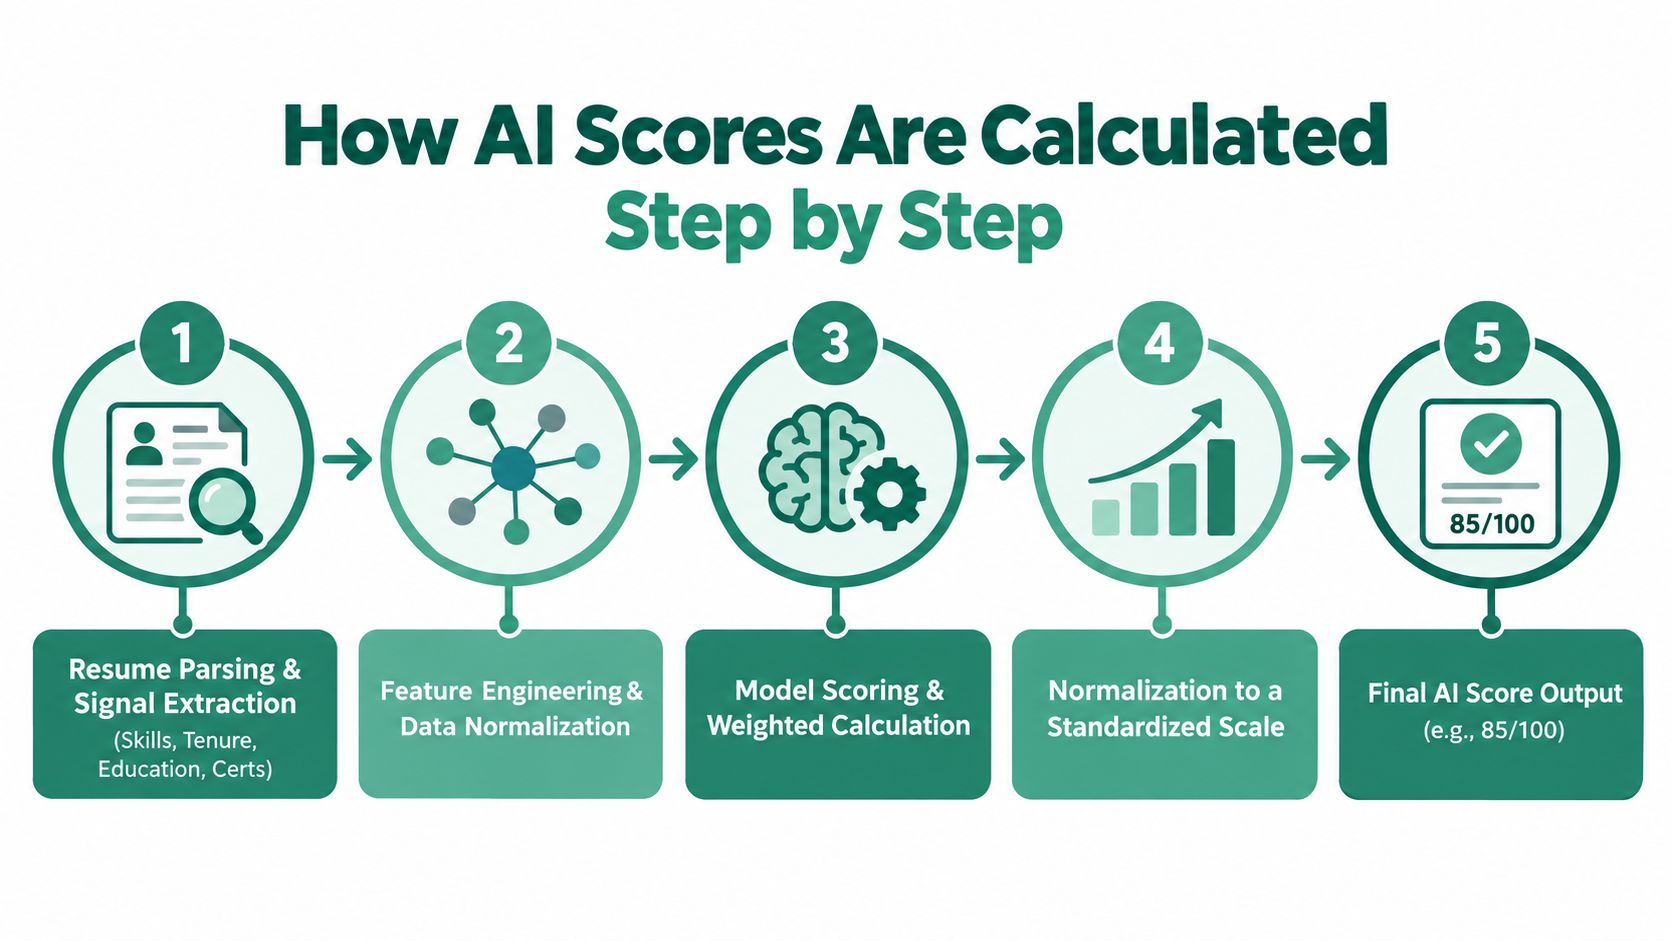
Resume parsing converts documents into structured fields. A system may identify skills, job titles, tenure patterns, education, certifications, industries, and project descriptions. It also has to normalize differences in wording. “Client success,” “customer success,” and “account support” may describe related work, but the system needs rules for deciding how those terms relate to the rubric.
Conversational screening adds another source of evidence. A candidate's answer may contain examples of handling escalation, using a specific tool, solving a technical problem, or communicating with a stakeholder. The system should connect that evidence to the criterion it measures, rather than treating every phrase as an equally important keyword.
A job analysis defines what matters for the role and how much each criterion contributes. A customer success manager rubric might assign weights to domain knowledge, problem solving, communication, retention strategy, and collaboration. Each criterion needs anchored examples, such as what weak, acceptable, and strong evidence looks like.
A weighted score can be represented as:
Final score = Σ criterion rating × criterion weight
Consider a purely illustrative customer success rubric with four criteria:
The weighted result is calculated by multiplying each rating by its weight, adding the products, and then converting the result to the employer's chosen scale. The example demonstrates the method, not a universal formula. A vendor should disclose its actual weighting and transformation rules.
Missing information shouldn't automatically become a low rating. The system might mark a criterion as unobserved, route it for human review, or apply a documented imputation rule. A resume without a named certification, for example, doesn't prove the candidate lacks the underlying capability.
A practical automated candidate screening workflow should preserve the original evidence, the criterion assessed, and the reason for the assigned rating. That record lets a recruiter examine whether the score reflects what the candidate submitted.
An absolute rubric score has a fixed meaning against the role standard. A relative rank score compares candidates with one another. Percentile scaling can make a candidate appear stronger or weaker depending on the current applicant pool, so recruiters need to know which type they're viewing.
Normalization also helps present results on a familiar scale, such as 0 to 100. It doesn't improve the underlying model. It only changes how the output is displayed.
A recruiter reading resumes quickly may rely on pattern recognition, professional experience, and instinct. That judgment can identify context a model misses, but it can also vary with fatigue, workload, recency, or the order in which applications appear.
Structured AI scoring makes a different tradeoff. It applies the same configured criteria to each candidate and creates a comparable record. The approach is strongest when the rubric reflects actual job requirements and weakest when the rubric encodes irrelevant or historically biased signals.
| Dimension | Structured AI Scoring | Unstructured Human Screening |
|---|---|---|
| Validity | Can test whether defined criteria relate to job outcomes | May recognize nuanced context, but often lacks a consistent validation record |
| Reliability | Repeated inputs can receive stable outputs when the system is calibrated | The same candidate may receive different judgments from different reviewers |
| Consistency | Applies the same rules across a large applicant pool | Depends on each reviewer's interpretation, attention, and workload |
| Contextual judgment | May miss unusual career paths or explanations not represented in the rubric | Can investigate rare signals and interpret exceptions |
| Candidate empathy | Offers standardized interaction | Can respond sensitively to personal circumstances and accommodations |
| Auditability | Can log inputs, criteria, scores, and overrides | Requires disciplined documentation to reconstruct decisions |
Imagine three human reviewers assess the same candidate pool and assign scores of 68, 79, and 87 to one applicant. A calibrated model assigns 78 to that applicant each time it receives the same evidence. The illustration doesn't claim that the model is more accurate. It shows why variance reduction matters.
Lower disagreement makes it easier to investigate adverse impact, identify inconsistent standards, and compare candidates against the same job criteria. It also makes a human override more meaningful because the reviewer can explain which evidence justified departing from the standardized result.
Structured interview research supports this focus on dependable measurement. One peer-reviewed study reported overall reliability of 0.83 for four interview scores and 0.86 for eight interviewer scores, while concluding that interviewers largely formed scores from a global impression rather than isolated item judgments. The study on structured interview scoring reliability reinforces a practical design principle for AI rubrics: common questions, anchored scales, and independent scoring produce more interpretable comparisons.
Practical rule: Use automation to standardize evidence collection, not to remove the recruiter's responsibility to interpret evidence.
Human screening still has an important role. A recruiter may recognize that a career gap reflects caregiving, that a nontraditional credential is highly relevant, or that a candidate's unusual project deserves a closer look. Structured scoring should make those judgments more disciplined, not eliminate them.
A vendor should be able to explain how its score was tested before asking an employer to use it. The first question is whether the validation sample resembles the people who will apply for the job.
SIOP guidance states that the validation sample for an AI-based employee-selection assessment must be representative of the applicant pool. The published validation guidance indexed by PubMed supports a direct procurement question: does the evidence cover the job families, locations, experience levels, and candidate groups that the employer expects to screen?
A model can appear accurate during development and fail in production if the development data underrepresent major groups or geographies. Buyers should request subgroup analysis of score distributions, selection rates, and predictive validity rather than accepting one overall performance statement.
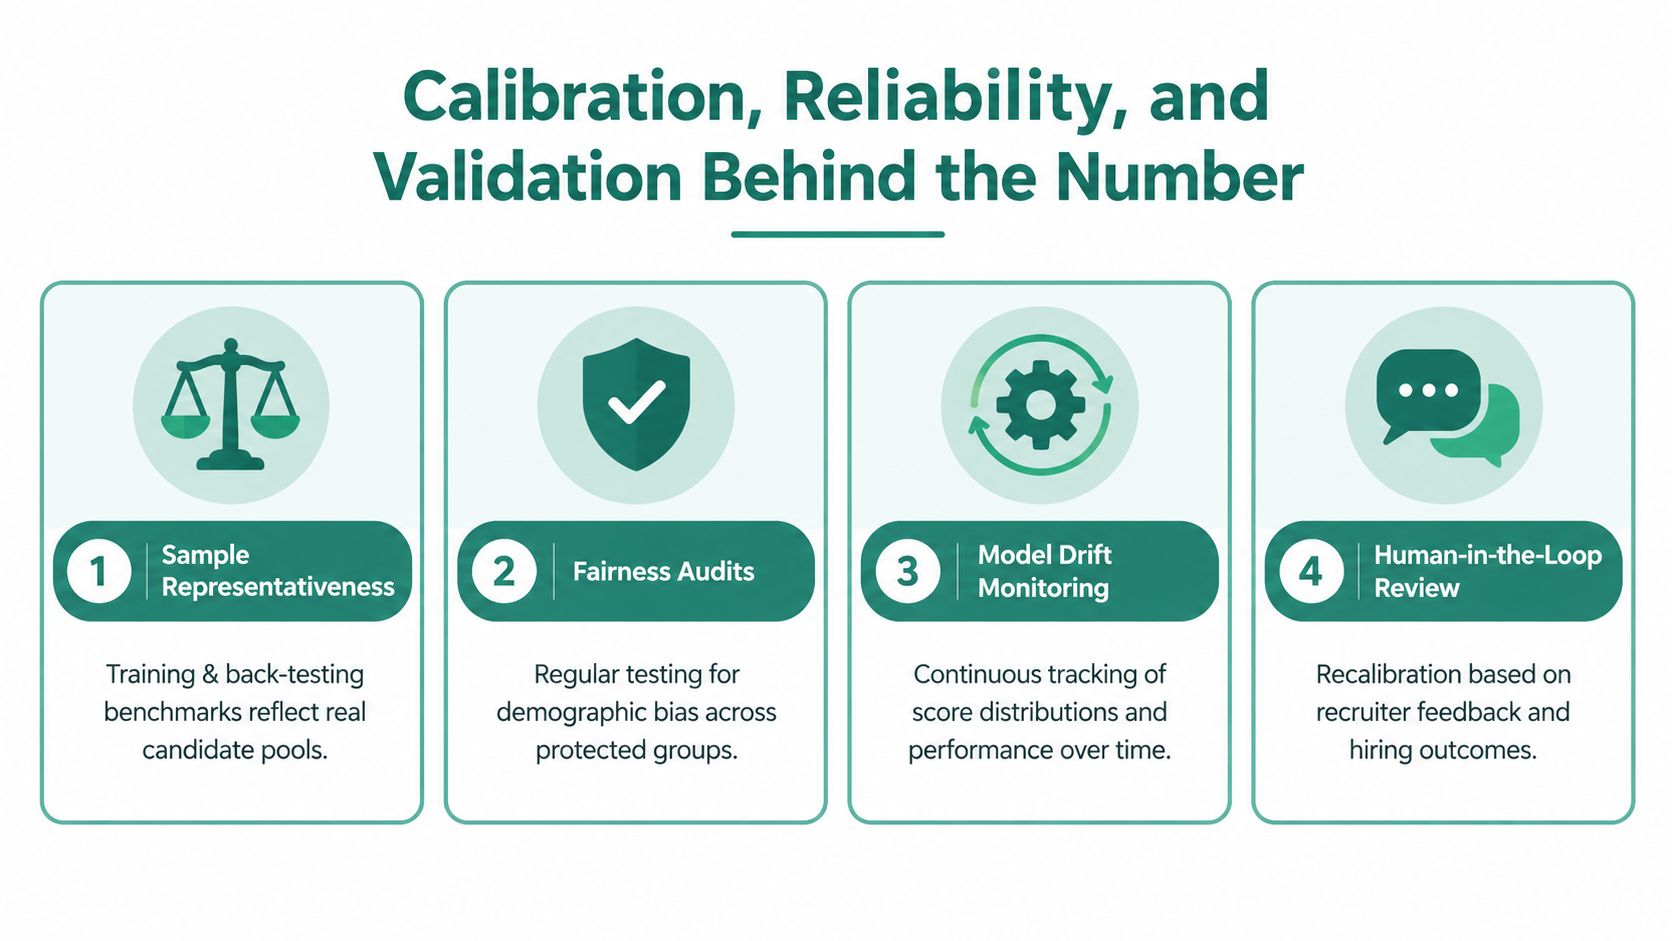
A practical validation review should include:
The exact sample size needed for a stable subgroup estimate depends on the role, outcome, design, and statistical method. A vendor that offers one universal minimum cell count without explaining those factors isn't giving a sufficient answer.
Employers should ask for adverse-impact ratios by protected group and by role, not only an aggregate result. The commonly used four-fifths benchmark is an impact ratio of 0.8, and a 2026 Warden AI audit summary covering more than 150 bias audits reported that 85% of audited systems exceeded that threshold across all tested demographic groups. It also reported an average AI selection impact ratio of 0.94.
The same summary reported 95% of systems scoring above 97.5% on counterfactual consistency, meaning outputs stayed stable when protected attributes were swapped in otherwise identical profiles. These results show what can be measured. They don't excuse an employer from testing its own roles and applicant populations.
Calibration should be repeated when score distributions shift, job requirements change, new data enters the system, or hiring outcomes diverge from expectations. A trustworthy vendor can explain the trigger, owner, evidence, and remediation process.
Passing an aggregate fairness test doesn't guarantee fair treatment for every job. A model can appear acceptable across a broad applicant pool while producing adverse impact in a particular role, job family, location, or hiring stage.
Independent coverage of a Stanford-linked study found that, among 4 million applications, the same screening model produced adverse impact in roughly 1 in 10 roles for Black applicants and 1 in 20 roles for Asian applicants. The coverage of role-level AI hiring bias illustrates why role-by-role auditing matters. An average can hide a serious pocket of harm.
Proxy variables can carry protected-attribute information even when the system doesn't use a protected field directly. Location, education prestige, employment history, language idioms, and resume formatting may correlate with demographic characteristics or unequal access to opportunity.
Historical labels create a different problem. If the model learns from past hiring decisions, those decisions become the target it tries to reproduce. A consistent model can therefore reproduce a consistent human bias unless the employer examines whether the label reflects job performance or merely prior preference.
Conversational scoring introduces additional concerns. Speech patterns, accents, speech disorders, disability-related differences, and second-language phrasing can affect automated interpretation even when they have no relationship to job capability. Text scoring can create similar problems when the model rewards a particular communication style rather than the role's actual requirements.
A 2026 qualitative review identified gaps including incomplete modeling of bias transmission, limited recruitment-specific fairness metrics, poor visibility into vendor algorithms, and very little longitudinal analysis of downstream effects. That means one audit snapshot cannot answer every fairness question.
| Check | What Vendors Usually Report | What Buyers Should Demand |
|---|---|---|
| Aggregate impact ratio | One result across all applicants | Results by role, subgroup, location, and hiring stage |
| Protected attributes | Direct fields were excluded | Proxy analysis and a clear feature inventory |
| Historical data | Model performance against past outcomes | Evidence that labels represent job-relevant outcomes |
| Conversation analysis | Overall completion or score stability | Testing for accents, disabilities, accommodations, and language variation |
| Audit timing | A pre-launch assessment | Ongoing monitoring and documented remediation |
| Candidate challenge | General support language | A real human review and correction process |
Before approving a vendor, an HR director should ask: Which features drive the score? Which features were removed, and why? What happens when a candidate requests an accommodation? Can the vendor provide role-level results? What evidence shows that a high score predicts a job-relevant outcome? The adverse-impact calculation guide can help hiring teams frame those questions in operational terms.
A score becomes useful only when the hiring team defines what action it permits. The safest approach is to treat bands as routing rules, not verdict boxes.
For illustration, an employer might configure:
Those ranges are a governance example, not a universal standard. An employer must set thresholds from role validation, business requirements, and fairness evidence. A number copied from another organization may have no equivalent meaning.
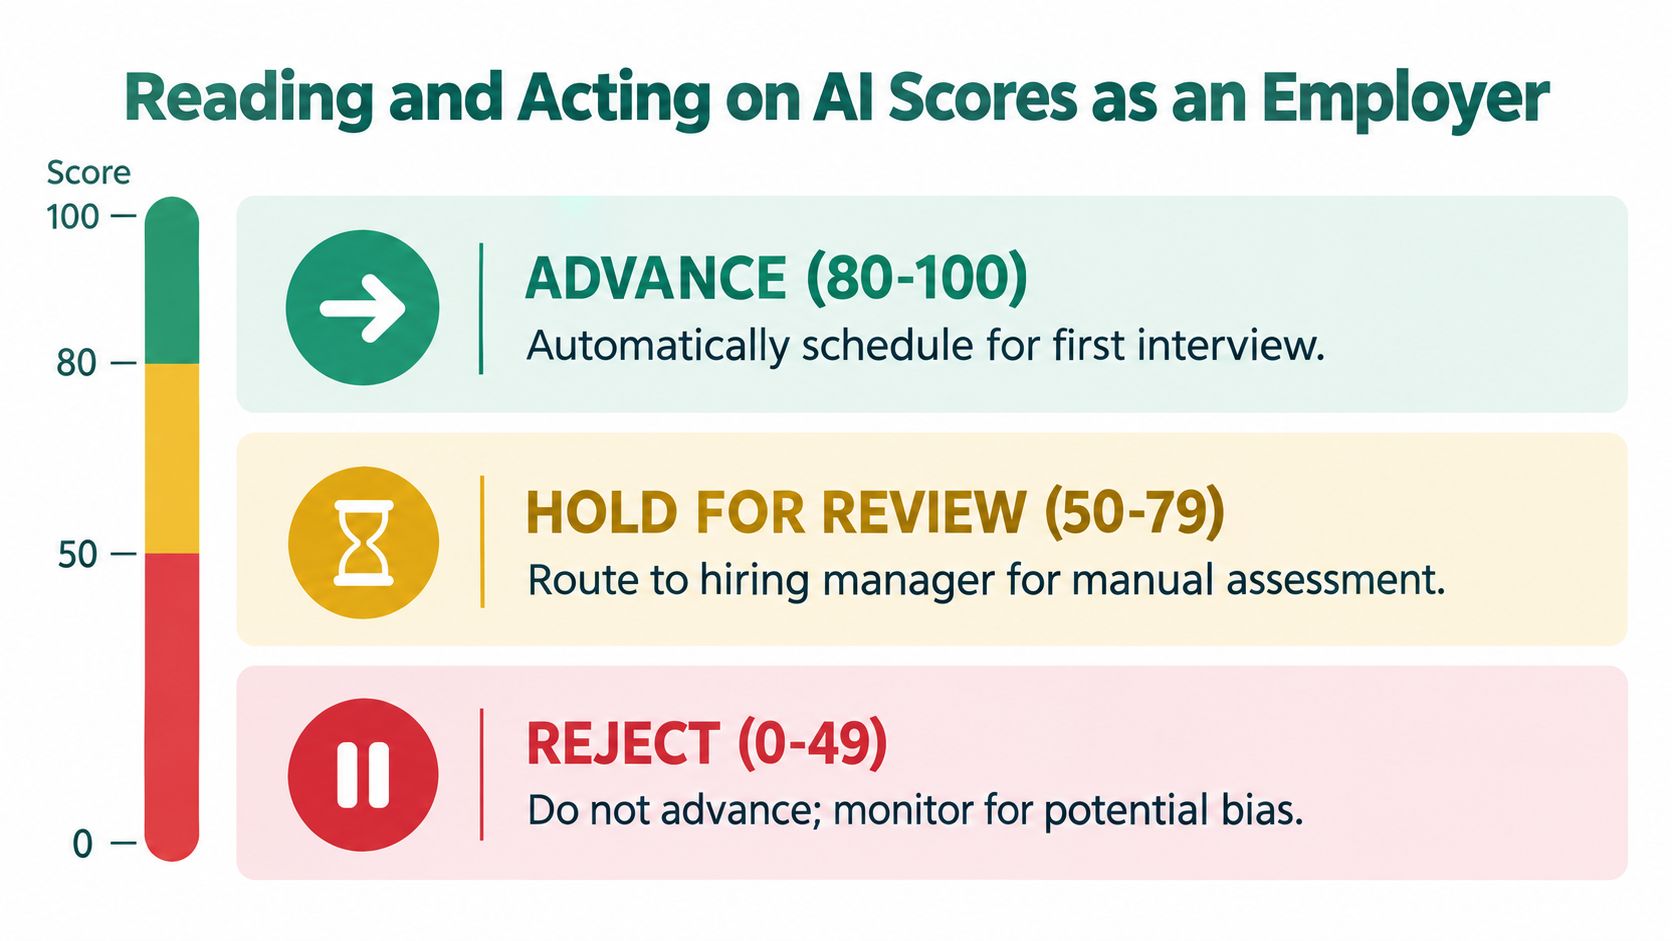
Automation can safely route clear matches to the next step when the employer has validated that workflow. Rejection requires more caution because missing data, proxy effects, and accommodation needs may lower a score without disproving capability.
Require human review for every rejection and for every borderline advancement. Let the score auto-advance only a clearly defined high-confidence match, with an audit log showing the evidence and rule used. The candidate ranking system guide provides a useful framework for separating ranking from final employer judgment.
Don't average numbers without understanding what they measure. A weighted composite can combine resume evidence, structured interview ratings, and job-specific assessments, but each component should have a documented purpose.
Use tie-breakers that relate to the role. If two candidates have similar composites, compare evidence for the critical competency rather than relying on a hidden model preference. When a reviewer overrides a score, require a reason code such as missing context, documented accommodation, incorrect parsing, or stronger job-relevant evidence.
Candidate rights and notice duties also belong in the operating procedure. Employers should review applicable requirements under NYC Local Law 144, the Illinois AI Video Interview Act, and the EU AI Act's high-risk classification for employment systems, including notice, explanation, assessment, and human oversight obligations where relevant. Legal teams should confirm how those rules apply to the employer's location, workflow, and technology.
A defined re-audit trigger is also necessary. If score distributions shift materially from one review period to the next, investigate the cause before continuing with the same thresholds. Don't treat a dashboard alert as a statistical conclusion. Treat it as a prompt to examine data, role mix, candidate behavior, and outcomes.
An HR lead can turn the mechanics into a week-one operating standard. Present the controls to procurement, legal, recruiting operations, and hiring managers before the first production rollout.
Document the inputs. Record every feature used by the score, the source of the data, the role criteria, and the weight assigned to each criterion. If a vendor can't explain what contributes to the result, the employer can't meaningfully audit it.
Require role-level subgroup testing. Ask for impact ratios by protected group and job family. Aggregate results may provide context, but they shouldn't replace the narrower analysis where hiring harm can occur.
Log every action. Store the score, supporting evidence, decision, and a reason code for both advancement and rejection. An audit trail should show what happened, who approved it, and whether the reviewer accepted or changed the automated recommendation.
Make overrides structured. A hiring professional should be able to override a score when the model missed relevant context, but the reviewer must document the job-related reason. Free-text explanations alone make later analysis difficult.
Require data provenance. Refuse a system that hides the origin, quality, or limits of its training and validation data. Commercial confidentiality doesn't justify withholding the information needed to assess job relevance and fairness.
Review outcomes over time. Compare score behavior with new-hire performance and retention at the employer's chosen follow-up points, including six-month performance review where that measure is available. Recalibrate when evidence shows drift, unexplained subgroup differences, or a mismatch between scores and job outcomes.
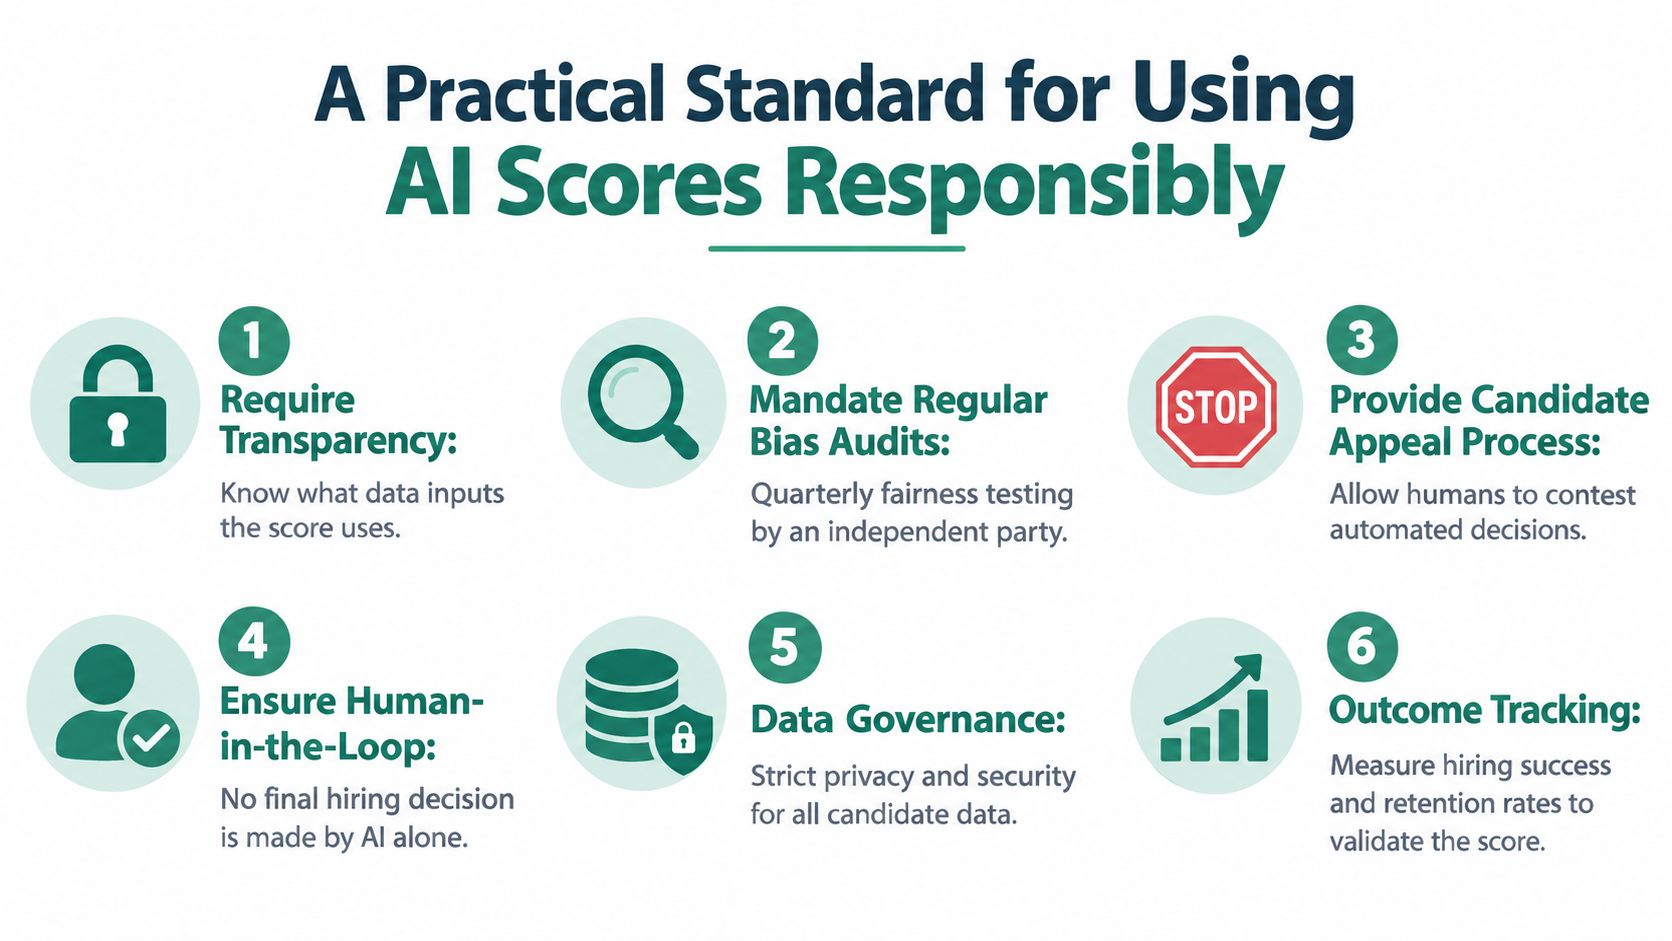
The standard should also define who owns each control. Recruiting operations can manage score logs and workflow rules. Legal can review notices, accommodations, and jurisdictional obligations. Hiring managers can validate rubrics and override reasons. Procurement can require documentation before contract approval.
An AI score is an audit-trail entry, not a substitute for professional judgment.
Structured interviews offer a useful foundation because every candidate receives the same predetermined questions in the same order and responses are evaluated with a standardized scoring system. Research summaries report predictive-validity coefficients around 0.51 for structured interviews compared with 0.38 for unstructured interviews in commonly cited comparisons, as summarized by Test Partnership's structured interview research. Other meta-analytic summaries report that combining a general mental ability test with a structured interview reaches validity of about 0.63, according to Sprad's review of structured selection methods.
The 2022 reanalysis by Sackett and colleagues is also widely summarized as reporting operational validity of r = .42 for structured interviews and r = .19 for unstructured interviews, as discussed in Agentr Global's research summary. These figures support structured evaluation, but they don't turn a score into certainty. Recent structured-interview fairness summaries also describe smaller adverse-impact differences for structured processes, reinforcing the need for common questions, common rubrics, and independent scoring.
Use AI scores to make evidence easier to compare, decisions easier to audit, and review work easier to prioritize. Keep the employer accountable for the decision.
Talent Pronto provides conversational screening, role-specific questions, structured candidate scorecards, and ranked shortlists while leaving advancement and rejection decisions with the employer. Visit Talent Pronto to see how its screening workflow can help your team evaluate applicants consistently and keep human review in control.

Talent Pronto is an AI-powered hiring platform built around Anna, our intelligent AI that conducts 24/7 conversational screening, evaluates candidates against specific job requirements and compliance needs, and schedules interviews. Run everything on the Talent Pronto ATS, our all-in-one applicant tracking system with a branded careers site and Anna built in, or keep your existing ATS and let Anna integrate with Greenhouse, Ashby, iCIMS, Jobvite, Lever, Oracle, and more. Either way, we help organizations reduce time-to-hire and build stronger teams.