Explore 8 rubric assessment examples for behavioral, technical, cultural, and compliance hiring, with scoring anchors and calibration tips.
A numerical score doesn't automatically make hiring objective. A rubric can give biased preferences a polished appearance, especially when evaluators score vague traits such as “culture fit,” “confidence,” or “passion” without defining the evidence that should earn each rating. Research on rubrics shows that reliability improves when criteria are analytic, topic-specific, and paired with exemplars or rater training, while a rubric alone doesn't guarantee valid judgment (research review of rubric design and scoring).
Useful rubric assessment examples connect role requirements to observable evidence. They distinguish must-have gates from weighted competencies, give evaluators consistent language for documenting decisions, and preserve human review instead of converting a score into an automatic hiring outcome. The eight examples below organize assessment around distinct hiring decisions, from behavioral evidence and technical depth to compliance risk, growth potential, and measurable outcomes. They also show how to customize anchors, calibrate evaluators, and use structured scorecards responsibly. Tools such as Talent Pronto can support role-specific questions and structured scorecards, while employers retain advancement and rejection decisions.
Behavioral competencies are useful only when they describe what a candidate did, not what an evaluator intuitively thinks the candidate is like. Communication, teamwork, problem-solving, and adaptability can support standardized comparisons, but each dimension needs observable anchors tied to the role.
A three-to-five-level scale can work well when the levels describe increasing evidence. A lower anchor for communication might show that the candidate gave an incomplete example and didn't clarify stakeholders, while a higher anchor could show that the candidate adapted a difficult message, confirmed understanding, and resolved a specific work problem. The score should follow the evidence in the response or work history, not the candidate's fluency, charisma, or familiarity with interview conventions.
A healthcare system may prioritize communication and empathy for nursing or patient-facing roles. A technology company may emphasize problem-solving and innovation across engineering positions. Retail and hospitality employers may need customer service and adaptability in fast-moving environments.
Keep the rubric focused. The planning guidance for this example recommends defining 5 to 7 core competencies per role, but that set should still reflect the most consequential success factors rather than every desirable behavior. Teams can use questions to assess decision making and adaptability to build prompts that expose those behaviors.
Useful operating practices include:
Conversational AI can probe for missing behavioral evidence, but it shouldn't infer a competency from tone or personality. The hiring team must decide whether the recorded behavior meets the job-related standard.
Practical rule: Limit each role to the competencies that most affect successful performance. More dimensions don't necessarily create a fairer decision.
A technical rubric should test performance, not familiarity with terminology. Keyword checks show that a candidate has encountered a tool, while realistic tasks expose technical depth, judgment, troubleshooting, and safe execution.
Start with the hiring decision. Identify which capabilities must be present on entry and which tools can be learned after hiring. Subject-matter experts and hiring managers can then divide broad domains into discrete skills and describe foundational, working, and advanced performance for the role. A candidate may explain a programming concept accurately yet produce difficult-to-maintain code, or name a cloud platform without diagnosing a deployment failure.
Use a scenario as the scoring anchor. For example, ask, “A production deployment fails after a configuration change. How would you isolate the cause?” Score the investigation sequence, test selection, explanation of trade-offs, and attention to recovery or prevention. Do not award points merely because the candidate uses a preferred phrase.
The rubric may cover:
Industry examples should change the anchors, not just the skill names. Healthcare roles may require evidence with Epic, Cerner, or another electronic health record platform. Manufacturing roles may assess CNC programming, PLC troubleshooting, and lean manufacturing certifications. Technology roles may examine programming languages, AWS, Azure, GCP, and DevOps tools. Pharma and biotech roles may require regulatory knowledge and analytical laboratory techniques.
Mark skills that affect safety, legal obligations, or immediate job performance as gates. Treat environment-specific tools as weighted competencies when the role allows learning time. Evaluators should review sample responses together, especially borderline cases, and record the evidence supporting each score. The scorecard organizes judgment; it should not convert an interview performance into an automatic hiring decision.
Technology changes can make examples obsolete. Update platforms and scenarios as the role evolves, while preserving the underlying capability being measured. This prevents vendor familiarity from outweighing durable technical judgment.
“Culture fit” can reward familiarity instead of job performance. A defensible rubric measures job-related values in action, while allowing candidates to contribute perspectives that differ from existing team norms. The hiring decision should therefore focus on observable behavior, not social similarity.
Start with the decision the rubric must support. A health tech startup might assess commitment to patient outcomes and healthcare access. A hospitality chain could examine customer-first behavior and relevant multilingual capability. Government agencies may assess service orientation and experience with diverse communities. Retail, hospitality, and manufacturing employers may value language, cultural, or community knowledge that helps them serve customers.
The University of Maryland ADVANCE research brief explains that templates, checklists, and specific criteria can reduce implicit bias, while warning that rubrics may still contain intrinsically biased criteria (brief on rubrics and bias in faculty hiring). Review every criterion for job relevance. Ask whether candidates can demonstrate it through different communication styles, and whether it rewards a dominant-group norm rather than a work requirement.
Define 4 to 6 concrete cultural pillars, then convert each into evidence-based anchors. For example, “collaborates inclusively” might require an example of inviting relevant expertise, handling disagreement, and sharing credit. Higher scores should describe specific actions and consequences. Lower scores should identify missing evidence, such as vague claims or no explanation of how the candidate treated others. Do not score accent, social similarity, or polished values language.
A culture fit assessment should clarify shared ways of working without preserving homogeneity. The scorecard structures judgment, but it cannot determine suitability automatically. Interviewers must inspect the evidence and challenge scores that appear to reflect personal preference.
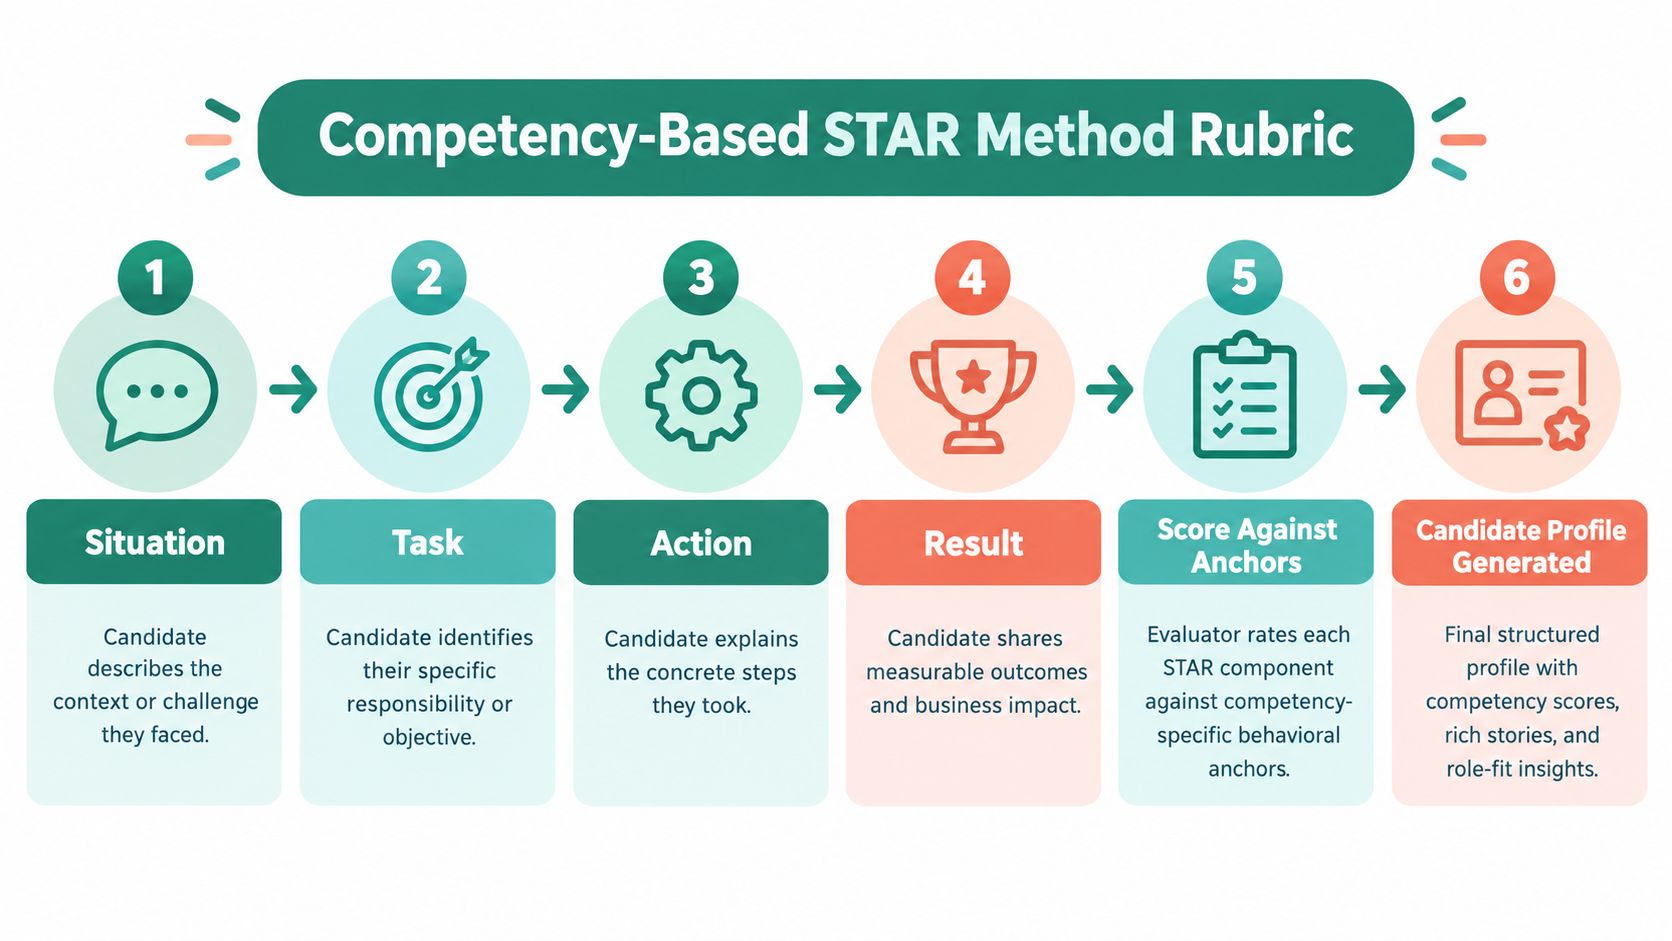
A polished STAR answer can conceal weak evidence. The Situation, Task, Action, Result structure should therefore support a hiring decision, not replace one. A candidate may describe an impressive outcome without showing personal ownership, or explain an action without defining the original problem. Score each component separately so fluent storytelling cannot compensate for missing evidence.
Build anchors around situation clarity, ownership, action specificity, and results. A high score requires a clear context, a personally owned objective, decisions the candidate controlled, and an outcome whose significance can be assessed. A low score may reflect repeated use of “we,” generic actions, unclear attribution, or no explanation of what changed.
The rubric should match the decision being made. Healthcare employers can examine clinical judgment and patient outcomes. Technology teams can assess problem-solving, project management, and innovation. Retail and hospitality employers can test responses to customer conflict and team leadership. Manufacturing employers can examine continuous improvement or safety decisions. These examples measure behavioral evidence, not storytelling style.
Use 4 to 6 competency-specific prompts tied to the role's success factors, then set follow-up questions in advance. Ask what the candidate personally changed, how the result was assessed, and what they would revise. Follow-ups should fill evidence gaps rather than steer candidates toward a preferred narrative.
A practical scorecard can weight:
Allow thinking time and accept concise answers. This reduces the chance that speed, accent, or verbal polish becomes an unplanned scoring criterion. Interviewers should compare sample responses before interviews, explain their ratings, and calibrate what counts as sufficient evidence. A scorecard organizes judgment; it does not make the hiring decision automatically.
Conversational AI can ask a follow-up when a STAR element is absent and preserve the transcript for review. Employers still need to verify attribution, context, and evidence before using the score. Interviewers seeking a consistent question sequence can use this guide to the STAR method for interviewing.
The following video can help interviewers standardize how they listen for structured behavioral evidence.
A requirements matrix should make two different hiring decisions visible: whether a candidate can proceed, and how strongly the candidate compares with others who pass. Some conditions function as pass or fail gates. A high overall rating cannot compensate for missing active licensure in a clinical role, an absent security clearance where it is required, or a safety condition the employer cannot waive.
The matrix should therefore begin with a short gate review, followed by weighted criteria for capabilities that can distinguish qualified candidates. Healthcare systems may check active licensure and relevant certification. Manufacturing employers may require CNC certification or substantial equipment-operation experience for a lead position. Technology companies may assess fluency in a specific programming language or a cloud certification. Government agencies may require security clearance or citizenship, while pharma and biotech employers may assess advanced academic preparation and regulatory knowledge.
A requirement belongs in the gate column only when the job, law, safety conditions, or operating model provides a clear reason. Hiring managers should review each proposed gate with subject-matter experts, compare it with capabilities shown by successful employees, and distinguish mandated conditions from preferences inherited from an old job description. Recheck the matrix as the role, technology, or labor market changes.
Use evidence fields beside each criterion: credential status, relevant experience, verification source, and reviewer notes. A candidate who passes every gate can proceed to weighted evaluation. A trainable gap should prompt human review, not automatic rejection. A true legal or safety gap should end the process with an accurate explanation. Someone who meets most requirements may fit an alternate role or development path.
Tell candidates which conditions are required when possible. This supports informed self-selection and limits wasted effort. Conversational screening can verify credentials early, but it should preserve the evidence and route exceptions to an employer for review.
The candidate screening matrix offers a starting structure for mapping requirements. Evaluators still need calibrated interpretations, job-related rationales, and periodic review. The matrix organizes evidence. It does not make the hiring decision automatically.
Compliance assessment should answer a practical question: can the candidate recognize and respond to risks that the role creates? It shouldn't become a trivia contest that rewards memorized regulatory language while ignoring judgment, communication, and execution.
Healthcare employers may assess HIPAA knowledge, patient safety protocols, and clinical compliance awareness. Pharma and biotech organizations may examine FDA regulations, GMP standards, and data integrity. Financial services and fintech teams may need AML, KYC, and broader regulatory knowledge. Government agencies may evaluate security-clearance suitability, conflicts of interest, and procurement compliance.
Start with compliance, legal, and quality specialists. Ask them to identify the obligations that are essential at each role level, then create tiered expectations. Entry-level candidates may need to recognize a risk and escalate it, while experienced candidates may need to investigate, document, and coordinate remediation.
A prompt such as “You notice a HIPAA breach. What do you do?” should score the candidate's sequence of actions. Strong evidence might include containing the issue appropriately, reporting through the correct channel, protecting affected information, documenting facts, and avoiding unsupported conclusions. The exact anchor must reflect the employer's policies and applicable requirements, not an invented universal response.
Verify certifications and training separately from interview answers. A credential check establishes one kind of evidence, while a scenario establishes practical judgment. Neither should replace assessment of the broader job responsibilities.
Update this rubric when regulations or internal procedures change. Conversational AI can identify knowledge gaps early and ask consistent scenario questions, but compliance specialists and hiring teams should review edge cases. The system should support documented, comparable evidence, not issue an irreversible decision based on a single answer.
Growth potential is easy to confuse with enthusiasm. A candidate who speaks energetically about learning may have less evidence of adapting than a quieter candidate who taught themselves a new system, recovered from a failed project, or transferred skills across industries.
Score observable learning behavior. Ask about a time the candidate had to learn something unfamiliar, what resources they used, how they handled uncertainty, and how their performance changed. Probe setbacks directly. The useful signal isn't whether the candidate claims to welcome failure, but whether they can explain what they learned and what they changed afterward.
A technology startup may need people who can scale with changing business demands. Healthcare systems may look for clinicians or administrators with leadership and innovation potential. Manufacturing employers can assess continuous-improvement behavior and lean-methodology thinking. Pharma and biotech organizations may value researchers who adapt as scientific priorities evolve.
Use several evidence channels:
Keep a separate score for current-role capability. Hiring for potential alone can leave a team without the skills it needs now. Career tracks can also recognize different forms of growth, including technical specialization and people management, rather than treating promotion into management as the only successful trajectory.
An outcome-based rubric evaluates impact, not activity. “Managed a project” says little by itself. A stronger answer identifies the relevant result, the candidate's contribution, the constraints, and the method used to achieve the outcome.
Choose 3 to 5 role-relevant performance indicators that reflect genuine success factors. Healthcare systems might assess patient outcomes, operational efficiency, and cost management. Technology teams could examine product adoption, revenue impact, or engineering velocity. Retail and hospitality managers may be assessed on sales, customer satisfaction, and labor-cost management. Manufacturing leaders might discuss safety, throughput, quality, and equipment uptime. Pharma and biotech leaders may need evidence involving project completion, regulatory submissions, and time to market.
Ask, “Tell me about a significant business result. What was the metric?” Then ask what changed because of the candidate's work, what other people contributed, and what constraints shaped the result. A candidate who inherited a high-performing operation shouldn't receive the same attribution as someone who diagnosed and corrected the underlying problem.
A fair scorecard also accounts for context. Support roles, career changers, and candidates from different industries may influence outcomes without owning the headline KPI. Look for credible evidence of contribution, such as improved processes, reduced risk, stronger service quality, or better team performance. Don't require every candidate to produce the same type of metric.
Conversational AI can probe unclear claims and ask for attribution, while humans decide whether the evidence is credible and job-related. For broader measurement guidance, see these data-driven employee performance tips.
| Rubric | 🔄 Implementation Complexity | ⚡ Resource Requirements | 📊 Expected Outcomes | Ideal Use Cases | ⭐ Key Advantages / 💡 Tips |
|---|---|---|---|---|---|
| Behavioral Competency Rubric | Moderate, define anchors, role customization, rater calibration | Moderate, HR/SMEs, rater training, periodic recalibration | Standardized behavioral comparisons; actionable feedback | Customer-facing, clinical, cross-role hiring, AI-guided interviews | ⭐ Consistency & bias reduction; 💡 Limit to 5–7 core competencies; calibrate quarterly |
| Technical Skills Proficiency Rubric | High, requires deep SME input and task-level indicators | High, technical tests, certifications, subject-matter experts, frequent updates | Objective assessment of technical fit; faster elimination of unqualified candidates | Engineering, IT, clinical systems, manufacturing, cloud/devops roles | ⭐ Measurable technical validity; 💡 Use scenario-based tasks; update as tech evolves |
| Cultural Fit, Values & Diversity Inclusion Rubric | High, design to separate fit from inclusion and avoid bias | Moderate‑High, DEI expertise, diverse panels, calibration | Better retention and team cohesion when inclusive; risk of homogeneity if poorly designed | Mission-driven orgs, customer-diverse roles, DEI-prioritized hiring | ⭐ Improves retention & DEI outcomes; 💡 Define 4–6 clear values; include bias safeguards |
| Competency-Based STAR Method Rubric | Moderate, structured STAR prompts and per-component anchors | Moderate, interviewer training, scoring guides, follow-up probes | Rich, evidence-based stories tied to outcomes; comparable candidate data | Leadership, project management, clinical decision-making, outcome-focused roles | ⭐ Strong evidence of past impact; 💡 Train probes for completeness; weight results heavily |
| Critical Role Requirements Matrix Rubric | Low–Moderate, decision trees and pass/fail gates; requires honest prioritization | Low–Moderate, SMEs to set deal‑breakers, automation for routing | Rapid triage; clear go/no-go decisions; transparent screening | High-volume hiring, roles with legal/certification must-haves, security-clearance roles | ⭐ Fast, transparent screening; 💡 Audit deal-breakers regularly; distinguish legal vs preference |
| Industry-Specific Compliance & Knowledge Rubric | High, legal/compliance input and scenario validation required | High, compliance/legal review, credential verification, frequent updates | Reduces regulatory risk; defensible hiring for regulated roles | Healthcare, pharma, finance, government, regulated operations | ⭐ Minimizes compliance exposure; 💡 Partner with compliance/legal and update quarterly |
| Growth Potential & Learning Agility Rubric | Moderate, create observable anchors for future-oriented traits | Moderate, behavioral probes, longitudinal tracking, calibration | Identifies high-potential hires for pipelines and mobility | Startups, growth-stage firms, succession planning, leadership development | ⭐ Good for long-term talent development; 💡 Balance potential with immediate role needs |
| Performance Indicators & Outcome-Based Rubric | Moderate–High, define KPIs, test attribution and context | Moderate, data collection, evidence validation, follow-up questioning | High predictive validity in results-driven roles; aligns hiring to business metrics | Sales, operations, product leadership, roles tied to measurable KPIs | ⭐ Strong outcome prediction; 💡 Define 3–5 KPIs, probe attribution, consider context |
A collection of templates won't create consistent hiring by itself. Research has shown that rubric-based scoring can vary by project type and assessment stage, with one study finding that rubric scoring accounted for 19.27% to 39.55% of total variance (study of rubric-based assessment variation). The finding matters because score differences can also come from raters, tasks, and interpretation. A rubric improves structure, but teams still need to test whether the structure measures what they think it measures.
Start by defining the role outcomes. Describe the work the person must perform, the risks they must manage, and the evidence a candidate could reasonably provide during the assessment. Then choose the smallest useful set of competencies. Separate essential gates from weighted dimensions, because a missing license, clearance, or safety requirement shouldn't be hidden inside an average score.
Write observable anchors for each score. A structured interview rubric commonly uses a 1 to 5 scale or descriptive performance levels such as below expectations through exceeds expectations (interview rubric guidance). The scale matters less than the descriptors. Each level should explain what evidence the evaluator should see, what evidence is insufficient, and how the role context changes the standard.
Test every question against the evidence it can produce. If the prompt invites vague opinions, replace it with a scenario or past-behavior question. If the answer depends on storytelling polish, add follow-up probes and pause tolerance. If two evaluators could reasonably interpret the same answer differently, rewrite the anchor or create an example response.
Run calibration sessions using representative responses, including strong, weak, incomplete, and ambiguous answers. Have evaluators score independently, compare rationales, and agree on the evidence that should control the rating. A 2007 review found that dependable performance scoring improves when rubrics are analytic, topic-specific, and paired with exemplars or rater training, while also emphasizing that rubrics alone don't ensure valid judgments (review of rubric reliability and validity).
After implementation, review score distributions, evaluator disagreements, candidate experience, and hiring outcomes. Look for criteria that almost everyone passes, criteria that produce persistent disagreement, and patterns suggesting that communication style or background is affecting scores. A University of Maryland guide recommends combining quantitative and qualitative ratings, which makes comparisons easier to audit and explain (guidance on clear evaluation criteria and rubrics).
Talent Pronto can support this operating model with role-specific conversational questions and structured scorecards. Its AI interviewer, Anna, conducts first-round screening against a job-specific rubric defined with the employer, while the employer remains responsible for reviewing evidence and making advancement or rejection decisions. Automation can standardize the early evidence collection, but accountability stays with the hiring team.
Talent Pronto provides 24/7 conversational screening, role-specific behavioral and technical questions, customized scoring rubrics, and structured candidate scorecards that support comparable early-stage evaluations. Visit Talent Pronto to explore how its screening workflows can help your team apply evidence-focused rubrics across high-volume hiring.

Talent Pronto is an AI-powered hiring platform built around Anna, our intelligent AI that conducts 24/7 conversational screening, evaluates candidates against specific job requirements and compliance needs, and schedules interviews. Run everything on the Talent Pronto ATS, our all-in-one applicant tracking system with a branded careers site and Anna built in, or keep your existing ATS and let Anna integrate with Greenhouse, Ashby, iCIMS, Jobvite, Lever, Oracle, and more. Either way, we help organizations reduce time-to-hire and build stronger teams.